



Live dashboard · Daily briefs · 简体中文

| 162 | 1086 | 180 | 48 | 5 | 0 |
|---|---|---|---|---|---|
| days live on a real HK + US account | decisions on the public ledger | episodes settled by code | data modules across 8 layers | agent harnesses, one contract | scores the model wrote for itself |
Numbers and charts refresh weekly; the live dashboard updates through the trading day.
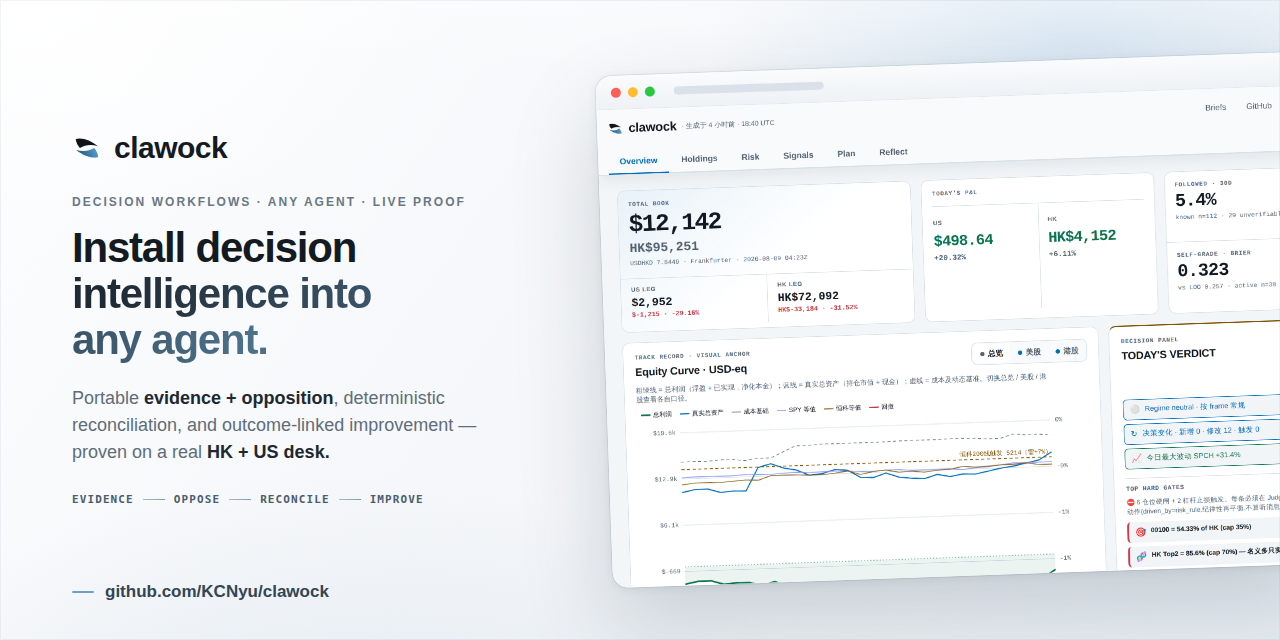
clawock helps your AI agent analyze your Hong Kong or US holdings and write a trading plan: buy, sell or wait, the case on both sides, and the prices that would change the call. You place the orders. Code later checks each call against market prices and saves the result for the agent to read next time.

That loop is what RSI, Recursive Self-Improvement, means here. Saved evidence and results give the agent something to review before its next decision. The author's daily jobs add connected data feeds, a scheduler and accumulated history; a new installation brings its own, or starts from the single-run example.
Important
This is not a promise of returns. The calls that told the author to act have not been shown to beat a coin flip.
One real call runs through this page: Goldwind (02208, Hong Kong) on the morning of 2026-10-08. The plan said keep holding and watch, add only above 8.97. The ledger records loss because the price fell by the next session's close; that scores the holding judgment, not a purchase at 8.97.
The plan's indicators came from plugins. A strategy may search for better settings of its own, but adopting them requires a person's review. Try it in five minutes.
Plugins compute the indicators; config/strategy-plugins.json selects the modules and their settings. Settlement and the ledger have no socket: a plugin cannot score its own call, choose its reference price, change the result or keep it off the ledger, so strategies are compared under the same rules. The figure follows the Goldwind call from one factors reading (no uptrend, 31.8% below the 200-day average) to its settled loss.

Every plugin declares its sources, units, observation periods and missing-data behavior before its results can reach a decision, so yesterday's result cannot be presented as today's.
| Plugin | Measures | When data is missing |
|---|---|---|
factors |
trend, momentum, RSI, volatility and an exit price for each stock, from daily prices | the field is empty; fewer than 30 daily prices means no result for that stock |
bar-signals |
how costly a name is to trade and how much it is likely to move, per session | empty, never zero: "could not be estimated" is not "cheap to trade" |
sentiment |
Reddit mentions over seven days, and statements by named public figures | the block is left out, and says whether the scan is missing, too old or unreadable |
morning-scans |
the macro snapshot and Chinese-language news, and the one read of every scheduled scan file | the same: left out, with the reason |
strategy-scores |
where each name ranks under each research strategy's current setting; reference only | says it is unavailable and why |
- If a plugin fails to load, only the tasks that need it stop, naming the plugin; other tasks keep running.
- Plugins change while others run. Removing one pauses its dependents and restoring it restarts them; a new setting restarts that plugin. This follows the dsh plugin design.
- You can write your own: register an installed Python module in the configuration file.

Warning
Plugins run with your permissions, not in a sandbox. Install only modules you trust.
clawock strategy-lab list       # plugins, their services and missing dependencies
clawock strategy-lab sources    # inputs, units, observation periods and missing-data behavior
Plugin configuration and boundaries · Write your own plugin.
clawock was never inside the chat. It is one skill (investment-decision), one command line tool and a handful of files in your workspace, so any agent that can read a file, write a file and run a command can use it: Claude Code / Codex / OpenClaw / DeepSeek Harness / your own script. Switch from Claude Code to Codex next month and, with the same workspace, the history comes with you.
Your agent keeps its model, conversation, memory, research tools, credentials and permissions; clawock never starts a model. It pins down what went in, checks what came out, marks the result later and keeps the record:
| File | Written by | What it holds |
|---|---|---|
request.json |
clawock, when you run clawock run prepare |
the material for this decision, with a fingerprint of every document so it cannot be swapped afterwards |
decision.json |
your agent | its answer: the case for, the case against, the action, and what would prove it wrong |
plan.json |
the author's setup, every morning | the same answer for a whole portfolio, one entry per position |
decisions.jsonl |
the author's setup | the public ledger: one line per decision, with the result added once code has marked it |
outcome.json |
you, once the waiting period is over | the prices you saw and where you got them |
evaluation.json |
clawock, when you run clawock workflow evaluate |
whether the direction was right. It is not money made |
The model itself does not change; the record does. Before the next plan the agent can review earlier judgments and their results, and with enough evaluated history the author's setup also checks how reliable earlier confidence figures were. A new workspace starts empty: you build the history by recording decisions and evaluating them.

Portable invocation and feedback protocol · Workflow improvement boundaries.
Sources are collected and labelled before anyone has an opinion. At 08:03 on 2026-10-08, before any model ran, Python had fetched Goldwind's daily bars, looked for a filing and pulled four headlines: two were about something else and two predated the previous close. No primary filing could be reached. The brief said so under 02208:
"This stock has no usable news evidence today, so today's judgment rests entirely on price and relative strength."
- Quote sources have fallback routes. Tencent or Nasdaq first, then the next provider; filings from the SEC and HKEX, capital flow from Eastmoney, plus news in two languages, macro data and sentiment. Python then reconciles the book, the exchange rate and the risk numbers.
- Old news is labelled old. Anything published before the previous close.
- A failed source says "not fetched", never "no news". Hong Kong has the basic coverage, but its research breadth is behind US.
What your agent receives is a pack of files, written by preflight on the author's setup or by clawock run prepare in yours, with a SHA-256 fingerprint of each document and of the whole. The Goldwind decision still carries the id of its pack, c3f65a7beaebb24e. Your own agent may add evidence from its research tools as long as it can be traced; the author's scheduled jobs read only the pack.
Note
The fingerprint proves which material was used, not that a news story is true. Each citation carries its source and time. Data-source passwords and your model API key stay in your own runtime.
The live desk's full information and delivery flow

Information layers and source catalog · Certification protocol.
The agent may not answer with a feeling. It writes the case for, then the strongest case against, and only then an action, its trigger price, a confidence figure and the condition under which it admits being wrong, all from the same pack. For Goldwind the 08:03 brief said: add above 8.97 within five sessions, invalid at 8.923. That day's high was 8.71, so the add did not trigger that day.
You get a plan and a receipt. Your agent writes decision.json and you run clawock run publish (the author's setup leaves the daily brief and plan.json). Python checks that every claim cites a document in the pack, that there is a case against and a condition that would prove the call wrong, and that order and currency arithmetic adds up. Pass, and the receipt is tied to that exact pack; without a case against, publication is refused. A verdict reached in conversation enters the ledger with clawock record --source <harness>. Either way, you decide which orders to place.

Example output, not a settled call.
The live desk's full bull / bear debate

On the author's setup four analysts, a bull and a bear researcher, three risk voices and a judge who names the strategy behind each call share the debate, adapted from TradingAgents. In your own harness, the one agent you have is held to the same two rules: read the same evidence, and write a case against.
Code settles every call on one standard set of daily bars, read on each market's own trading calendar. Goldwind's reference was 8.645, the first tradable price after publication; the next session closed at 8.28, down 4.22%, so the record is a loss. It is a watch scored as passive_stance with fill_assumed: false: a score for the holding judgment, not profit or loss from a new trade. Every call is settled this way and published, wins, losses and ungradeable alike; nobody adjusts a result afterwards.
- Saying the same thing every day counts once. From 2026-07-29 to 2026-10-08 the brief said "hold and watch" on Goldwind 45 times. That is one result (
ep-f31982c6d511), not 45. - A call that cannot be graded stays on the ledger. On 2026-10-01 Hong Kong was closed, so record
dec-143614125e34hasoutcome: unknown,status: not_evaluableandsession_reason: market_closed. - What you did is recorded apart from what the plan said.
clawock mark-followedmarks each call followed or not.
The next decision starts from this record. The 2026-10-12 brief printed the Goldwind call under "Yesterday's results" with loss beside it, and the model reads how reliable its earlier confidence figures were, using earlier dates only. In your own harness: observed prices go in outcome.json, and clawock workflow evaluate writes evaluation.json, which checks direction, not realized profit.

Results or a rejected publication can support a proposal to change the evidence requirements: only the required evidence count and the confidence limit without a primary source, never strategies, trading rules or the skill. A named reviewer's decision is recorded before it applies, and it can be rolled back (feedback protocol).

Cumulative episode win rate against a 50% directional-hit line: how often the direction was right, not what it earned. Refreshed weekly by GitHub Actions; live figures are on the Holdings tab.
Caution
Read the scorecard with these limits.
- It measures direction, not money. Keeping the model away from its own score stops it grading itself; it does not make the market data or the definitions correct.
- The calls to act have not been shown to beat a coin flip. A signal whose measured range still includes 50% is kept out of decisions, and the leverage dial's timing cannot be told apart from chance. Both are published in Reflect.
- The shadow portfolio is a simulation. Its headline leaves out commission and spread; a second figure with a cost deduction fixed in advance sits beside it. Neither models market impact.
- The account's result is yours plus the model's. Every call carries its status: followed, not followed or unknown.
With ledger data you can redo the sums: clawock scorecard-provenance --check rebuilds each published headline number from memory/decisions.jsonl, and clawock audit-resettle settles the whole ledger again. How grading handles the hard cases · what we tested, and what failed.
A proposal is scored on more than whether it paid. On 2026-10-12 the model proposed trimming 20 shares of MiniMax (00100) above 225 and gave 0.55 to a close under 213 on the fifth session. Code kept the proposal (prop-7c966b4a33172e8c) with its inputs, its named method and two objections, then reads it twice, separately: did the trade pay, and was 0.55 a fair probability. Method evaluation reports both; a method that scores well is not promoted automatically.

The rsi plugin is configured for a 14-session look-back read as a rebound signal. After the morning brief the strategy lab tests other settings; the 2026-10-12 run covered the 28 stocks with price history, Goldwind included.
- Only declared settings are tried. Six look-backs by two readings, and all twelve are counted, so a lucky result cannot pass as the only one.
- A gate judges the best one: enough untuned days, a ranking that beats chance and the current setting by more than noise, a low chance of fitting the past, and adjusted prices. Configuration can make it stricter, never looser than the floor in the code.
- Second opinions may block, for example after trading costs. They cannot pass what the gate refused.
- Every verdict goes to a ledger, checked against these rules each time it is read.
- Then it has to keep working. A passing setting is scored only on days that had not happened when it was picked.

The 2026-10-12 answer: a 28-session look-back read as "strength continues" would have ranked these names better, and it was registered. The same search on the 16 names whose prices the provider confirmed as adjusted, Goldwind one of them, was refused, so every run now carries that second search.
Note
The search did not change Goldwind's RSI settings. Adoption is a reviewed configuration edit, which the lab may propose only after the candidate holds up over at least 60 later sessions and passes the check it currently fails. As of the 2026-10-12 run, neither had happened.
clawock strategy-lab evolution rsi   # each run, what changed, each registration and how it has done since
clawock strategy-lab row-edits       # proposed configuration changes, for review
clawock strategy-lab verify          # the ledger against the lab's limits
What a search may conclude, second opinions and the lab's limits.
The model writes opinions. The arithmetic and the score run in Python and are unit-tested. On the Goldwind morning the model could not:
- Choose its own reference price. 8.645 came from a rule: the first price that could be traded after the plan was published.
- Mark its own call.
losswas written by the settlement code from the daily bars. - Publish without a case against. It is refused, as the five-minute run shows.
- Add Hong Kong dollars to US dollars. The two currencies sit side by side with the exchange rate and its timestamp.
- Decide whether a risk limit has been crossed. Code checks the limits at every brief; that morning it found four position limits and two leverage stop-losses crossed, and the brief opened with them. Each breach keeps a dated record of how it was answered. None sells anything by itself.
All twelve rules, and what the code does for each.
With dsh and the host runner configured, you can hand over a task and come back to the result. Ask for a repository change in the dsh web GUI; a background agent (Claude Code, Codex or OpenCode) keeps working after you close the tab, and the panel shows how far it got. clawock-dsh is one npm package with four parts, each needing a little more of the host:
| Part | What you see | What it needs |
|---|---|---|
| Investment skill and Decision Mind | The agent walks the decision steps; a tab traces each real fill from plan to P&L | dsh |
| Provider panel | Claude and Codex allowance windows, DeepSeek and MiniMax balances, the OpenCode free pool, in the sidebar | dsh |
| Dispatch queue | Each agent's queue in real order, task details and controls, patrol, a seven-day stats card, the ops version footer | clawock's agent-dispatch runner on the host |
| Chat commands | /dispatch-list and /dispatch-stats in WeChat or Telegram, read-only |
the package loaded as an OpenClaw plugin |

- See what is happening. Subscription use and resets, provider balances, each agent's real queue, model, elapsed time and API-price cost estimate share one panel.
- Change course while it runs. Reorder waiting work, change the next attempt's model where allowed, adjust deadlines and retry budgets, cancel or retry.
- Keep the result in reach. A completed task with a failed send stays visible.
From the queue to a task's history

Task completion and message delivery are separate: this finished task has a failed Telegram receipt. Full queue capture · Full task history.
The close of the panel: patrol and the week

- Patrol is one row with the last eight rounds; it opens a page with every round.
- The week is one card: tasks, tokens and an API list-price estimate, not what a subscription is charged.
- The footer says which code is running.
ops <hash> · runner api <n>turns red when merged code is not installed.
In chat, /dispatch-list prints the panel and /dispatch-stats the week. Full stats page · Full patrol page · Queue capabilities and setup · runner and ops contract.
Note
The author's host maintains its own code through the same queue: patrol rounds check published outputs, a filing gate checks each finding's evidence before an issue is opened, and a background agent takes the fix through a PR and required CI. Installing the Python package or dsh plugin does not set up these patrol rounds.
Four coding agents, one memory, and a history of every change

A rule Claude Code wrote down in the afternoon reaches a Codex task the queue starts overnight, with nothing copied across: every agent's instruction file links to one shared file, and every task starts in the same home folder. ops/host/install_shared_memory.sh installs the skill, memory.py and memctl; every write is a commit naming the agent and task. Two limits remain: only Claude Code loads the index when it starts, while the other three search it when a task needs it, and Codex's own memory feature stays off. You get the mechanism, not anyone's notes: a fresh install starts empty. How the shared memory works.
Decision Mind traces a real fill through plan → execution → T+1 → P&L: what the plan said, what you did, where the price was one session later and what it earned or lost. A fill with no plan, or not yet graded, says so; a new workspace has no trades to show. Ask "Can I add to 0700.HK?" and the investment skill walks the agent through the same steps as above.

python -m pip install clawock
dsh plugin --profile web add clawock-dsh
mkdir -p ~/.dsh/skills
cp -r ~/.dsh/profiles/web/node_modules/clawock-dsh/skills/investment-decision ~/.dsh/skills/
Restart the web profile to load it. Queue controls also need the host runner; without it the panel still shows provider allowances and balances. For the chat commands, add the installed package directory to OpenClaw's plugins.load.paths and restart the gateway. npm package · installation and queue setup.
These diagrams show the author's configured account: market-data access, holdings, stored decisions, scheduled jobs and delivery destinations. Installing clawock gives you the commands and workflows; a daily service like this one needs those inputs and jobs configured too.


The pre-open job starts at 08:03 HKT on an OpenClaw schedule. Every job has three steps: clawock … preflight collects the files, the model writes, and clawock … postflight checks and publishes what it wrote.

Rendered from the host's real openclaw cron list --json by site/tools/shoot_openclaw_cron.js; job ids, delivery targets and prompts are left out. The full timetable is the generated schedule.
How the desk works covers the information layers, run context, settlement rules and code gates.
Choose the agent you already use; each logo opens a runnable integration example. These are five alternative ways to use the same workflow, not five agents installed by the package.


You need Python ≥ 3.11 and an agent that can read and write files. Start in an empty directory:
pip install clawock
clawock workflow install investment-decision --workspace ./my-book
clawock init ./my-book --workflow investment-decision
cd my-book && mkdir -p .clawock/work
clawock run prepare > .clawock/work/request.json
# your agent reads the installed skill and request, then writes decision.json
clawock run publish --request .clawock/work/request.json --artifact decision.json=decision.json
This creates a workspace and validates a decision; add your own holdings and evidence for a real one. It does not install the author's data feeds, history or schedules. The model call and its costs stay in your runtime; clawock is free and open source. CI runs these commands from the installed wheel in a clean environment.
Tip
No model or credentials? Clone this repository and run bash examples/cli/minimal-run/run.sh from its root. It publishes a fixed test answer in a temporary environment; isolated run published <run_id> confirms the basic check, not an investment analysis. Or open a Codespace:

Drop the opposing evidence from decision.json and publish refuses it (exit code 1):
{
  "status": "rejected",
  "validation_issues": [
    {"code": "insufficient_opposing_evidence", "message": "requires at least 1 opposing evidence item(s)"},
    {"code": "unsupported_bear_case", "message": "bear_case must cite opposing evidence"},
    ...
  ]
}
The whole run inside Claude Code, from the examples/claude-code instruction:

- Live dashboard — positions, risk, and the code-graded scorecard.
- Daily briefs — the published morning reads.
- Decision Map — a dated signal snapshot beside each decision (reading guide).
- Examples by harness — one decision run, five harnesses, plus the npm dsh plugin.
- How the desk works — the information layers, what each run reads, decision gates, grading rules and the twelve code-enforced rules.
- Intraday research workflow — intraday cards keep historical research apart from conditional order suggestions for manual confirmation; no order is ever submitted.
- Influencer radar — eight public sources scanned twice a trading day and linked to holdings; misses are published as misses.
- Command reference · glossary · all project docs · contributing
| Question | Entry point | Reuse scope |
|---|---|---|
| Analyze a US company | us-stock-analysis |
Reusable with the clawock workspace |
| Analyze a Hong Kong company | hk-stock-analysis |
Reusable with the clawock workspace |
| Review the current portfolio | portfolio-risk-review / portfolio-swarm-review |
Specific to the configured portfolio |
| Stress-test a supply-chain thesis | serenity-skill |
Reusable as a manual research framework |
| Review a reported quarter | earnings-review |
Reusable; artifacts live in memory/earnings/ |
| Decide whether a new name is worth researching | entry-gate |
Reusable; artifacts live in memory/entry-gates/ |
They expect clawock's scripts, data contracts and memory files; they are not standalone one-command products.
Warning
This repository holds real trading positions. It is not investment advice, a recommendation, or a copy-trading system. clawock analyzes and proposes; it does not place orders for you.
It is one person's record and a workspace you can take with you. No result is hand-picked: the settlement rules and every change of method are versioned in code. The calls to act have not been shown to beat a coin flip, and every number may be out of date by the time you read it.
Original code is under the MIT License. Adapted third-party code keeps its own license and attribution in NOTICE and THIRD_PARTY_LICENSES/. Third-party market data, news, social posts, filings, trademarks, and API access are not relicensed by MIT — see Third-party data and services.
Built with Claude Code, the openclaw cron daemon, a static Jekyll + GitHub Pages frontend, and Python. Market, news, macro, and sentiment come from documented public sources; see third-party data and service terms before reusing any fetched content.


