MiniMax H3 でリップシンクしてみました
あいさつ
前回の記事で、ACE-Step 1.5 を使って2曲できあがりました。今回はこの曲にあわせて AI で生成した人物たちに映像出演してもらいましょう。実際の動画はこの記事の最後にてご覧ください。
登場人物と背景の準備
1曲目はソロ、2曲目はデュエットなので、合計3人(女性2人と男性1人)を用意します。
また、それぞれ別のステージを割り当てるので、背景も2枚用意します。
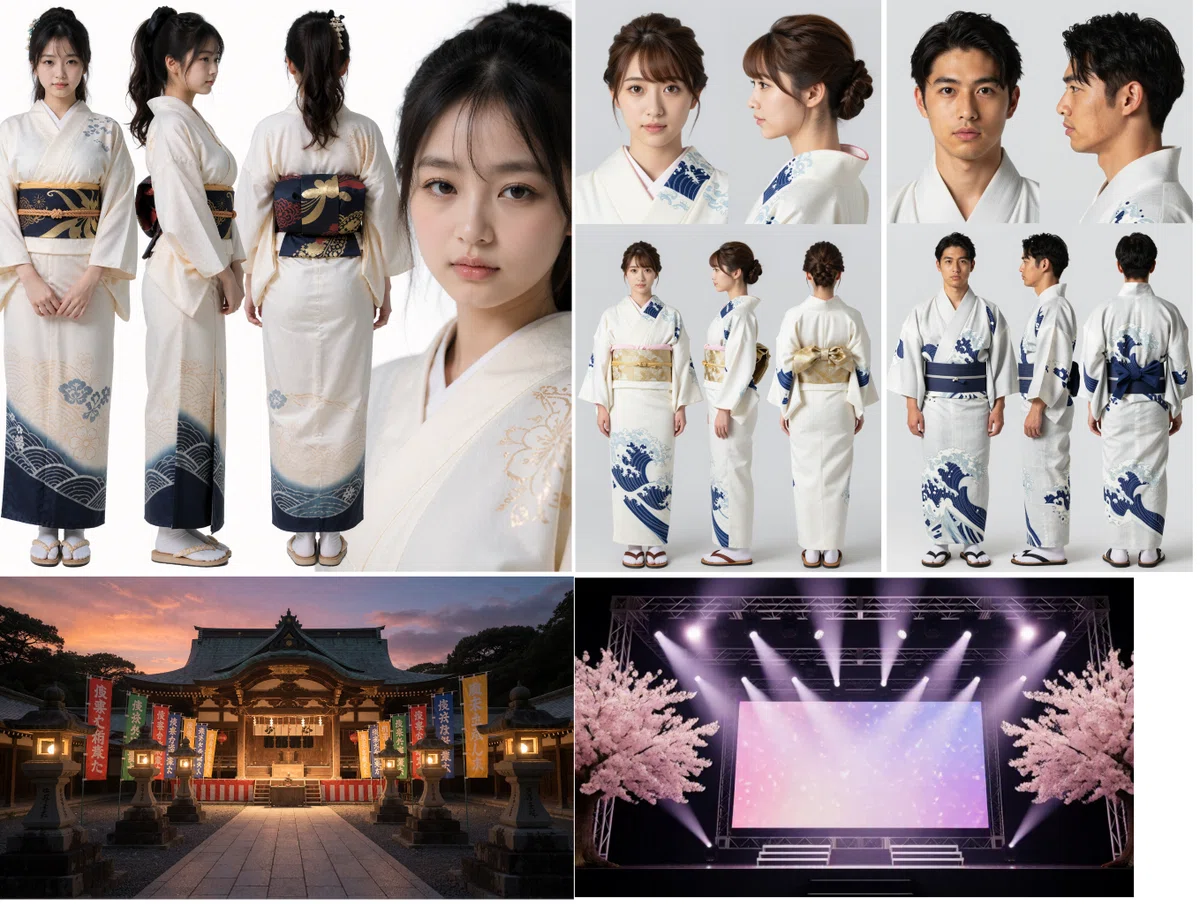
ソロの女性の画像のフォーマットを変えてみました。Krea 2 Turbo で、モデルを MoodyKrea2Mix_v20、
LoRA に IndonesianK2 (0.50)、krea2_9d6_FigureCrafter_v1 (0.50) を加えて、以下のプロンプトで生成しています。画像サイズは 2048x2048。
masterpiece, best quality, 8k resolution, photorealistic.

A grid layout divided into four vertical sections. From left to right: full-body front view, full-body side view, full-body back view, and—on the far right—a close-up shot of the face from a three-quarter angle. Clean white background, consistent character design, model sheet, official art style, hyper-detailed, high-quality, crisp lines.

A 15-year-old Japanese girl with fair skin, authentic Japanese facial features, a round face, and brown eyes. She is visibly busty. She wears a white traditional silk furisode kimono, subtle makeup, refined posture, featuring a navy and white wave pattern, paired with a sash displaying a bold gold and madder-red design. Her long black hair is tied up in a high ponytail adorned with a hair accessory, and she wears a gentle expression, wearing traditional Japanese zori sandals, white tabi socks,
二人目・三人目は Z-Image Turbo の AuraFlow というワークフローにて生成。画像サイズは 1024x1920。(Negative Prompt は省略)
A character reference sheet set against a light gray background, featuring views from multiple angles.
The top row displays two detailed close-ups—a frontal view and a left profile—that clearly show facial features and expressions.
The bottom row presents full-body standing poses (showing the overall silhouette): a front view on the left, a side view in the center, and a back view on the right.
The image features consistent character design, sharp focus, and high definition, photorealistic.
20歳の日本人女性。色白の肌、アーモンド形の茶色い瞳が特徴。
紺と白で描かれた波模様がさりげなく片側の袖と裾にあしらわれた白を基調とした浴衣を金色を基調とした帯で着用し、髪はかんざしを飾った古典的なアップスタイルに結っています。
穏やかな表情を浮かべています。男性部分の特徴記述は以下のとおり。浴衣の帯の描写も変更しています。こちらも画像サイズは 1024x1920。
30歳の日本人男性。恰幅の良い体形。少し日焼けした、つやのある肌、細長い目と黒い瞳が特徴。口をあけると大きそうに見える口と分厚い唇。シーザーカットの黒髪。
紺と白で描かれた波模様がさりげなく片側の袖と裾にあしらわれた白を基調とした浴衣を、灰色と紺色を基調とした男物の帯で着用しています。
にこやかな表情を浮かべています。
背景画像の神社は再び Krea 2 Turbo にて、モデルの MoodyKrea2Mix_v20 だけで生成したものを、画像編集ソフトで縦横それぞれ約70%だけのサイズで中央部分を切り取っています。
masterpiece, best quality, 8k resolution, photorealistic.

A festival stage set up within the precincts of a Japanese shrine at dusk. The sky is a beautiful twilight blend of orange and purple. Stone lanterns, their lights aglow, line the approach, while colorful festival banners flutter in the breeze.
背景画像の室内ステージは、前回の動画でも利用した MiniMax H3 の text to image のワークフローにて以下のプロンプトで実行。
Masterpiece, 8K resolution, super detailed, photorealistic,

コンサート用に設置されたステージを正面から移したもの。ステージは金属トラスで構成されており、背後のホリゾンタイルスクリーンには淡いピンクと紫の紙吹雪が描かれており、お祭りの雰囲気を醸し出しています。ステージ全体も紫色の光で埋められています。ステージの両脇にはピンク色の花を咲かせた大きなさくらの木があり、現場に彩りを添えています。ステージの両端の木の後ろはステージの袖が黒い幕でおおわれています。フレームの上方からはいくつものスポットライトがステージのあちこちに降り注いでいます。ステージがより際立ちます。画像全体の雰囲気はエネルギッシュでお祝いの雰囲気です。
リップシンクの準備
MiniMax H3 の ref2va のワークフローに追加あるいは変更した点として、
ref_audio_0 に接続するオーディオの読み込みのノードには、start time と duration が設定できて曲の一部だけを取り出せるものを採用しています。(「Comfy-VideoHelperSuite」の「Load Audio (Upload)」
普通は「VAE Decode Audio」の「samples」に繋いでいる音声のラインですが、オーディオ読み込みのノードから直接、「Create Video」等の「audio」へ繋いで、途中で曲を加工されないようにします。
動画生成後(VAE Decode の後)に「Get Image from Batch」のノードを追加して、batch_index を -1 にします。その後ろに「Save Image」のノードを追加して、その画像を保存するようにします。
今回のリップシンク動画を作成するにあたって、ワークフローでは以下のように参照画像と曲を設定します。
<Picture 1> 前回の動画の最後のフレーム(※ 最初の動画では OFF)
<Picture 2> 背景のステージ画像
<Picture 3> 女性のキャラシート
<Picture 4> 男性のキャラシート(※ソロの場合は OFF)
<Audio 1> 曲
【注意!】 プロンプトで指示していないノードは無効化しておかないと、知らないうちに参照される恐れがあります。
次に、曲のどの部分でカットしてつないでいくかを歌詞と見比べながら決めていきます。
1つの区切りが長くなると、生成時間がひじょうに多くかかるようになり、短いとあとで動画編集の際のつなぎの作業が大変です。
今回は各曲の1番だけについて、以下のように分けました。(2曲については前回の記事を参照)
※ 5~7秒で区切れればよいのですが…。
●1曲目(ソロ)
00.0 - 09.5 (9.5) : イントロ
09.5 - 12.0 (2.5) : 歌いだし
12.0 - 19.8 (7.8) : 1番A
19.8 - 28.0 (8.2) : 1番B
28.0 - 38.0 (10.0) : 1番サビ
●2曲目(デュエット)
00.0 - 01.7 (1.7) : イントロ出だし
01.7 - 05.2 (3.5) : イントロ掛け声
05.2 - 09.8 (4.6) : 1番A1
09.8 - 13.8 (4.0) : 1番A2
13.8 - 17.5 (3.7) : 1番B1
17.5 - 21.5 (4.0) : 1番B2
21.5 - 24.0 (2.5) : 1番掛け声
24.0 - 32.0 (8.0) : 1番サビ
リップシンク(最初のショット)
1曲目の最初の部分のプロンプトは以下のとおり。
subject_definitions:
<Subject 1> is the woman in <Picture 3>. Her facial identity, facial structure, skin tone, hairstyle, age appearance, body type, and body proportions come exclusively from <Picture 3>. She is also the speaker (S1).
<Audio 1>: fully_copy - <Audio 1> is reused 1:1 as the target video's complete final audio track, (S1) sings a song.
<Subject 3> is the environment as the stage shown in <Picture 2>.

summary:
[Reference Generation]
Generate a cinematic shot of <Subject 1> as the main subject, for music video, highly detailed hyper-realistic texture, stunning 8k resolution, photorealistic.
<Subject 1> is singing in Japanese on a center of the field shown in <Picture 2> as the stage, incorporating gestures that synchronized with the audio in <Audio 1>, accompanied by gestures.
Lip movements are synchronized with the rhythm and vocals.
The shot is a cinematic medium shot characterized by natural head movements, expressive and emotive motion, intricate lighting, and stable facial features.

Retention Analysis:
<Subject 1>: Fully retained – The woman's facial features, bone structure, hairstyle, perceived age, body shape, and physical proportions from <Picture 3> are consistently maintained across all shots.
<Picture 2>: Fully retained as the stage.

detailed_description:
[Shot 1]
The camera gradually zooms in on <Subject 1>, starting with a full shot and transitioning to a medium shot.
With the tip of a slender, inconspicuous, skin-colored headset microphone resting against her cheek, she walks slowly from off-stage right to the center of the raised stage, then stops and turns to face the audience, and bows.
<Subject 1>'s mouth remained closed.

overall_soundscape:
<Audio 1> only, copied exactly as the complete final audio track. No additional speech, ambience, crowd noise, instrument sound, or sound effects.

non_diegetic_music:
<Audio 1> only.
[Shot 1] だけにしていることと、カメラの指定を入れています。
また、最初なので、歌手の女性 <Subject 1> が小さな肌色のヘッドセットマイクを頬の横につけていることを明示しています。次回からはこの動画の最終フレームを利用するので、画面から消えていないかぎりはこの表現は不要になります、たぶん。
このパートではイントロを聞くだけで歌わないので、「<Subject 1>'s mouth remained closed.」(口は閉じたまま)としています。
あとこの女性の動き、ステージの中央に歩いてきて、一礼するという表現も入れましたが、尺が足りないと画面の端からでてこないで、最初からステージ上に現れています。このあたりの動きの違いについては、高速化のために使用している turbo_4step の LoRA や Sampling, Attention などのモデル周りに挟み込んでいるノードが影響しているものと思われます(未検証)。
★ もしプロンプトで指示した動作が曲の時間内に終わらなかったら?
曲はいきなり無音になりますが、動作が終わるまで映像は続くようです。
最後のフレームの画像を保存していますが、音が終了する直前の画像とは食い違うため、動画編集で次のパートにつなごうとしたときに、それぞれの動画の最後と最初の映像が一致しないことになります。
念のため、動画が生成されるごとに、音の最後と映像の最後のずれを動画編集ソフト等で1コマずつ確認したほうがよいかと思われます。あるいは、編集時にトランジションでごまかす手もあるかと思います。私は今回の動画生成では無視しています。
なお、今回のやりかたでは、最終フレームの画像をつなぐため、途中のパートだけをやり直すことは基本的にできなくなります。また最初からやり直しになるのでつらいです。
パート(ショット)ごとにカメラワークを切り替える手法のほうが簡単ですね。
リップシンク(2つ目以後のプロンプト)
さきほど保存された最後のフレームの画像を <Picture 1> にセットします。
プロンプト内の「subject_definitions:」のあとに次の行を追加します。
<Picture 1> is the exact first frame of [Shot 1] at 00:00.000.[Shot 1] の直後に次の行を追加します。
The shot begins from <Picture 1> as the exact first frame at 00:00.000.
あとは1つ目と同様に歌詞にかかわる部分を変更していけばよいです。
歌詞に関しては、以下のような書き方で、このパートに出てくる歌詞を伝え、また、正確に口パクする指示を入れます。
<Audio 1> is the Japanese song with the lyrics <d>[Japanese]・・・</d>.

The mouth of (S1) movements are precisely synchronized with the Japanese lyrics.
実際のプロンプトがこちら。
subject_definitions:
<Picture 1> is the exact first frame of [Shot 1] at 00:00.000.
<Subject 1> is the woman in <Picture 3>. Her facial identity, facial structure, skin tone, hairstyle, age appearance, body type, and body proportions come exclusively from <Picture 3>. She is also the speaker (S1).
<Audio 1>: fully_copy - <Audio 1> is reused 1:1 as the target video's complete final audio track, (S1) sings a song.
<Subject 3> is the environment as the stage shown in <Picture 2>.

summary:
[Reference Generation]
Generate a cinematic shot of <Subject 1> as the main subject, for music video, highly detailed hyper-realistic texture, stunning 8k resolution, photorealistic.
<Subject 1> is singing in Japanese on a center of the field shown in <Picture 2> as the stage, incorporating gestures that synchronized with the audio in <Audio 1>, accompanied by gestures.
Lip movements are synchronized with the rhythm and vocals.
The shot is a cinematic medium shot characterized by natural head movements, expressive and emotive motion, intricate lighting, and stable facial features.

Retention Analysis:
<Subject 1>: Fully retained – The woman's facial features, bone structure, hairstyle, perceived age, body shape, and physical proportions from <Picture 3> are consistently maintained across all shots.
<Picture 2>: Fully retained as the stage.

detailed_description:
[Shot 1] The shot begins from <Picture 1> as the exact first frame at 00:00.000.
The mouth of (S1) movements are precisely synchronized with the Japanese lyrics.
<Audio 1> is the Japanese song with the lyrics <d>[Japanese]
ハー サテモ!
</d>.

overall_soundscape:
<Audio 1> only, copied exactly as the complete final audio track. No additional speech, ambience, crowd noise, instrument sound, or sound effects.

non_diegetic_music:
<Audio 1> only.
およそ期待した感じの動画が仕上がってくれば、あとは続きをどんどん生成していけばよいかと思います。それぞれのチェックは忘れずに。
※ 英語版なんかだとすなおに音声ファイルからリップシンクしてもらえるようですが…。
また、音声ファイルを直接動画に放り込まないで、従来通り「VAE decode audio」などを通すと、よくわからない言語になったりします。
デュエットの場合
こちらの最初のパートのプロンプトです。
まずは、[Shot 1] にある「Their initial relative positions are as shown in <Picture 1>.」の行を削除してから実行し、動画の中で二人の動きがよければそれでよし。もし二人が離れている状態のままであれば、よい感じになるまで再実行してみました。二人の間隔がよくなれば、そのときに実行してできた最後のフレームを <Picture 1> にセットして、先ほど削除した行を復活させた後、もう一度実行しました。
※ このパートは 1.7秒と短いので何回か試してもそれほど時間がかかりません。
subject_definitions:
<Subject 1> is a woman in <Picture 3>. Her facial identity, facial structure, skin tone, hairstyle, age appearance, body type, and body proportions come exclusively from <Picture 3>. She is also the speaker (S1).
<Subject 2> is a man in <Picture 4>. His facial identity, facial structure, skin tone, hairstyle, age appearance, body type, and body proportions come exclusively from <Picture 4>. He is also the speaker (S2).

<Audio 1>: fully_copy - <Audio 1> is reused 1:1 as the target video's complete final audio track, (S1) and (S2) sing a song.
<Subject 3> is the environment as the stage shown in <Picture 2>.

summary:
[Reference Generation]
Generate a cinematic shot of <Subject 1> and <Subject 2> as the main subject, for a part of music video, highly detailed hyper-realistic texture, stunning 8k resolution, photorealistic.
<Subject 1> and <Subject 1> are singing in Japanese on a stage shown in <Picture 2>, incorporating gestures that synchronized with the audio in <Audio 1>, accompanied by gestures.
Their lips movements are synchronized with the rhythm and vocals.
The shot is a cinematic medium shot characterized by natural head movements, expressive and emotive motion, intricate lighting, and stable facial features.

Retention Analysis:
<Subject 1>: Fully retained – The woman's facial features, bone structure, hairstyle, perceived age, body shape, and physical proportions from <Picture 3> are consistently maintained across all shots.
<Subject 2>: Fully retained – The man's facial features, bone structure, hairstyle, perceived age, body shape, and physical proportions from <Picture 4> are consistently maintained across all shots.
<Picture 2>: Fully retained.

detailed_description:

[Shot 1]
The camera captures full-body shots of the two singers standing on stage.
Their initial relative positions are as shown in <Picture 1>.
Each of them holds a wireless microphone in one hand, moving their bodies and their other hands in time with the rhythm.

<Subject 1> and <Subject 2>'s mouth is closed.

overall_soundscape:
<Audio 1> only, copied exactly as the complete final audio track. No additional speech, ambience, crowd noise, instrument sound, or sound effects.

non_diegetic_music:
<Audio 1> only.
上のプロンプトでは、ソロの場合と同じように、口を閉じている指示と、こちらはワイヤレスマイクを片手に持って、もう片手はリズムを取っているという指示にしています。
次のパートのプロンプトです。([Shot 1]の部分だけを抜粋)
[Shot 1] The shot begins from <Picture 1> as the exact first frame at 00:00.000.
The camera is taking a medium shot of <Subject 1> and <Subject 2>.
Each of them holds a wireless microphone in one hand, moving their bodies and their other hands in time with the rhythm.

<Subject 2>'s mouth is closed at first.
<Audio 1> is the Japanese song with the lyrics.
The mouth of (S1) movements are precisely synchronized with the Japanese lyrics. <d>[Japanese]ハー</d>.
Upon finishing the song, <Subject 1> closes their mouth and lowers the microphone to chest level.
The mouth of (S2) movements are precisely synchronized with the Japanese lyrics. <d>[Japanese]ソレソレ</d>.
続いて、さらに次のパート。
[Shot 1] The shot begins from <Picture 1> as the exact first frame at 00:00.000.
The camera slowly zooms in on <Subject 2>, capturing a close-up of his face from an angle from the current position.
Each of them holds a wireless microphone in one hand, moving their bodies and their other hands in time with the rhythm.

<Subject 1> initially keeps their mouth closed (silent) and lowers the microphone to chest height, holding it there.
The mouth of (S2) movements are precisely synchronized with the Japanese lyrics. <d>[Japanese]むかしながらの かいどうぞいに</d> in <Audio 1>.
こんな感じで最後までプロンプトを作って実行していきます。
動画の結合
それぞれのパーツの動画ができあがったら、AviUtl でけっこうシンプルに結合しました。
デュエット曲でのプロンプトの難しさは、二人のそれぞれの歌詞の指示と、歌っていない間の動作を記述することですかね。
時間があればもっとカメラワークに凝ったりしてみたいところです。
巷では MV のような動画を作る話をよく見かけますが、マイクを持っておとなしくステージで歌うのも、これはこれでありかと思います。
ではお目こぼしかもですが、ご覧ください。
ということで、MiniMax H3 でリップシンクしてみました編でした。
