And how we can turn that feeling into insights
And how we can turn that feeling into insights
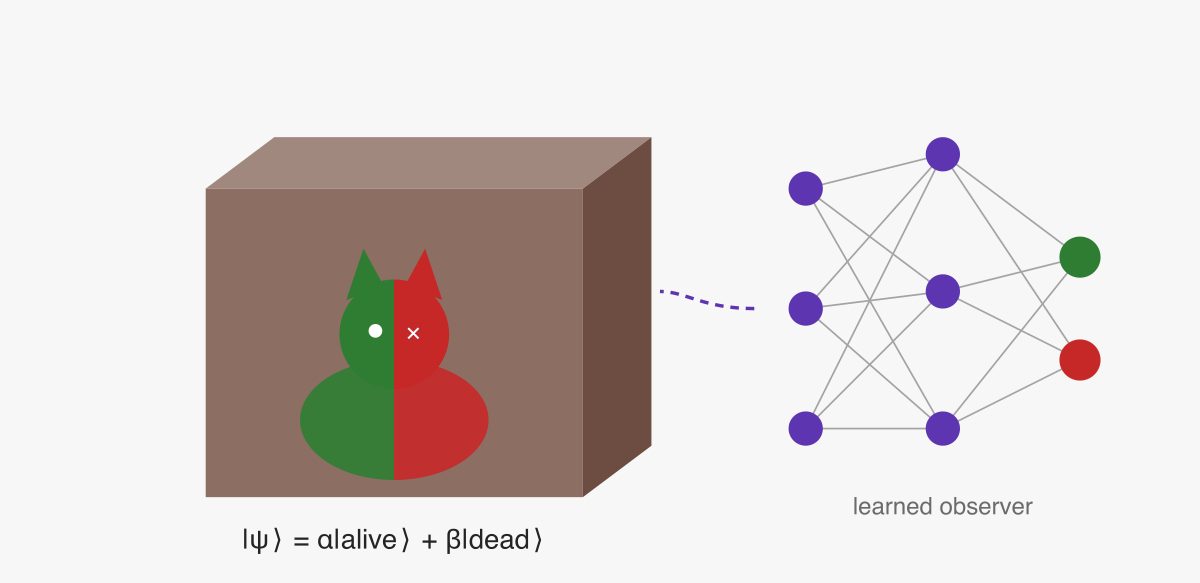
Neural networks won’t settle the measurement problem — but they are quietly changing how we see, predict and protect quantum superpositions.
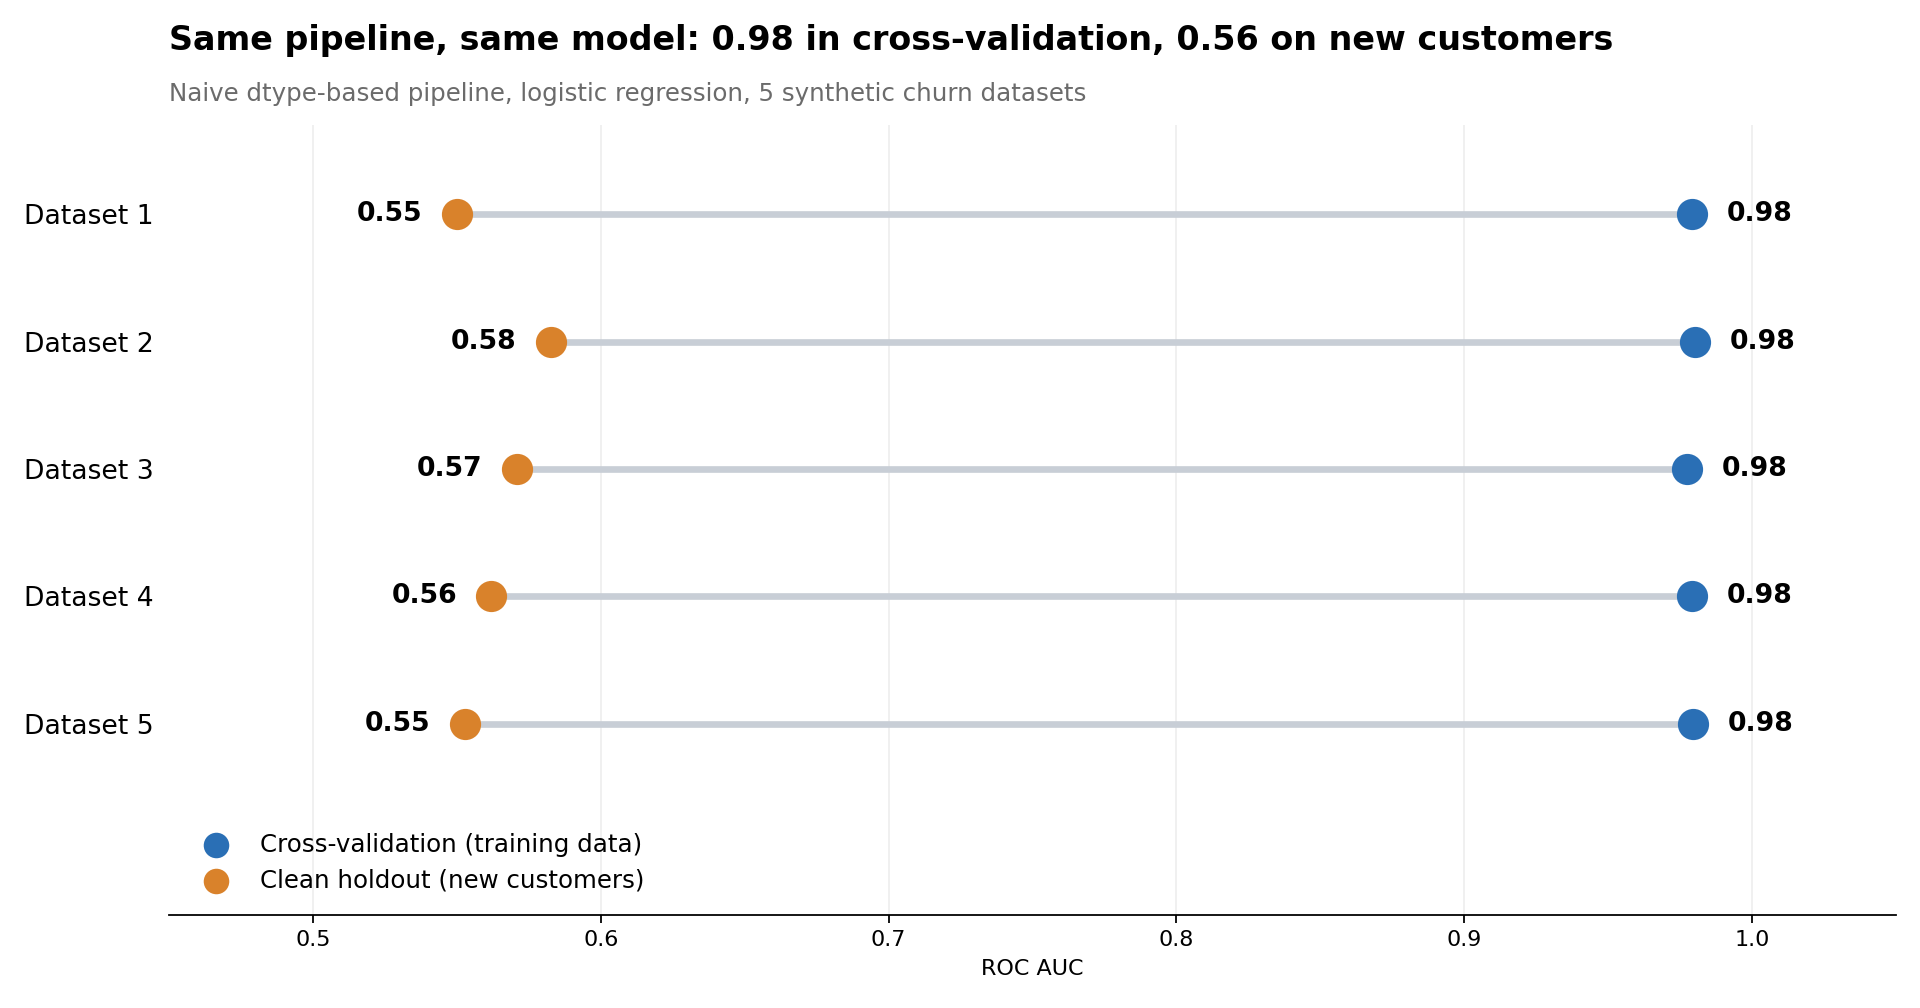
What an ID column, a date string, and a missing value taught me.
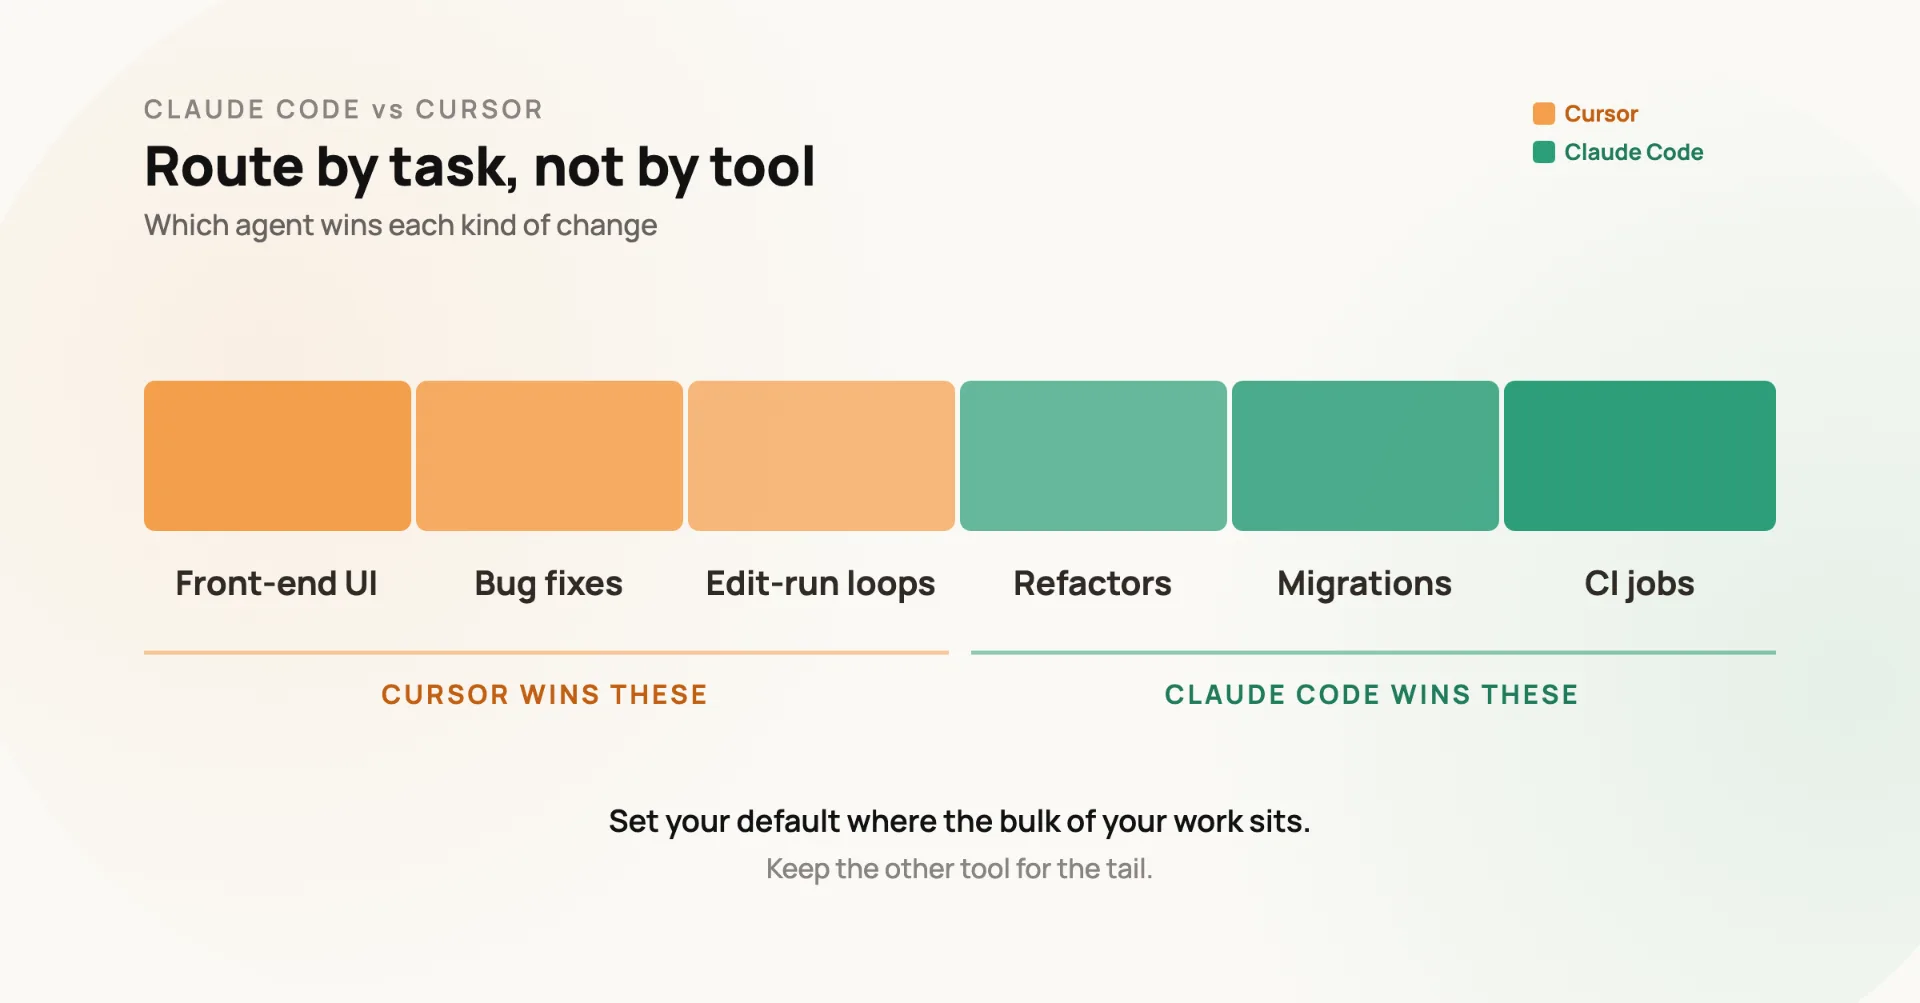
One benchmark says Claude Code used 33,000 tokens where Cursor used 188,000. Another says the exact reverse. Here is the field test that actually settles it for your team.
When a tool breaks, an agent can keep going and write a confident answer from nothing while the dashboard stays green.
Beyond naive chunk-and-embed: Six production architectures for turning enterprise lakehouses into governed AI platforms.
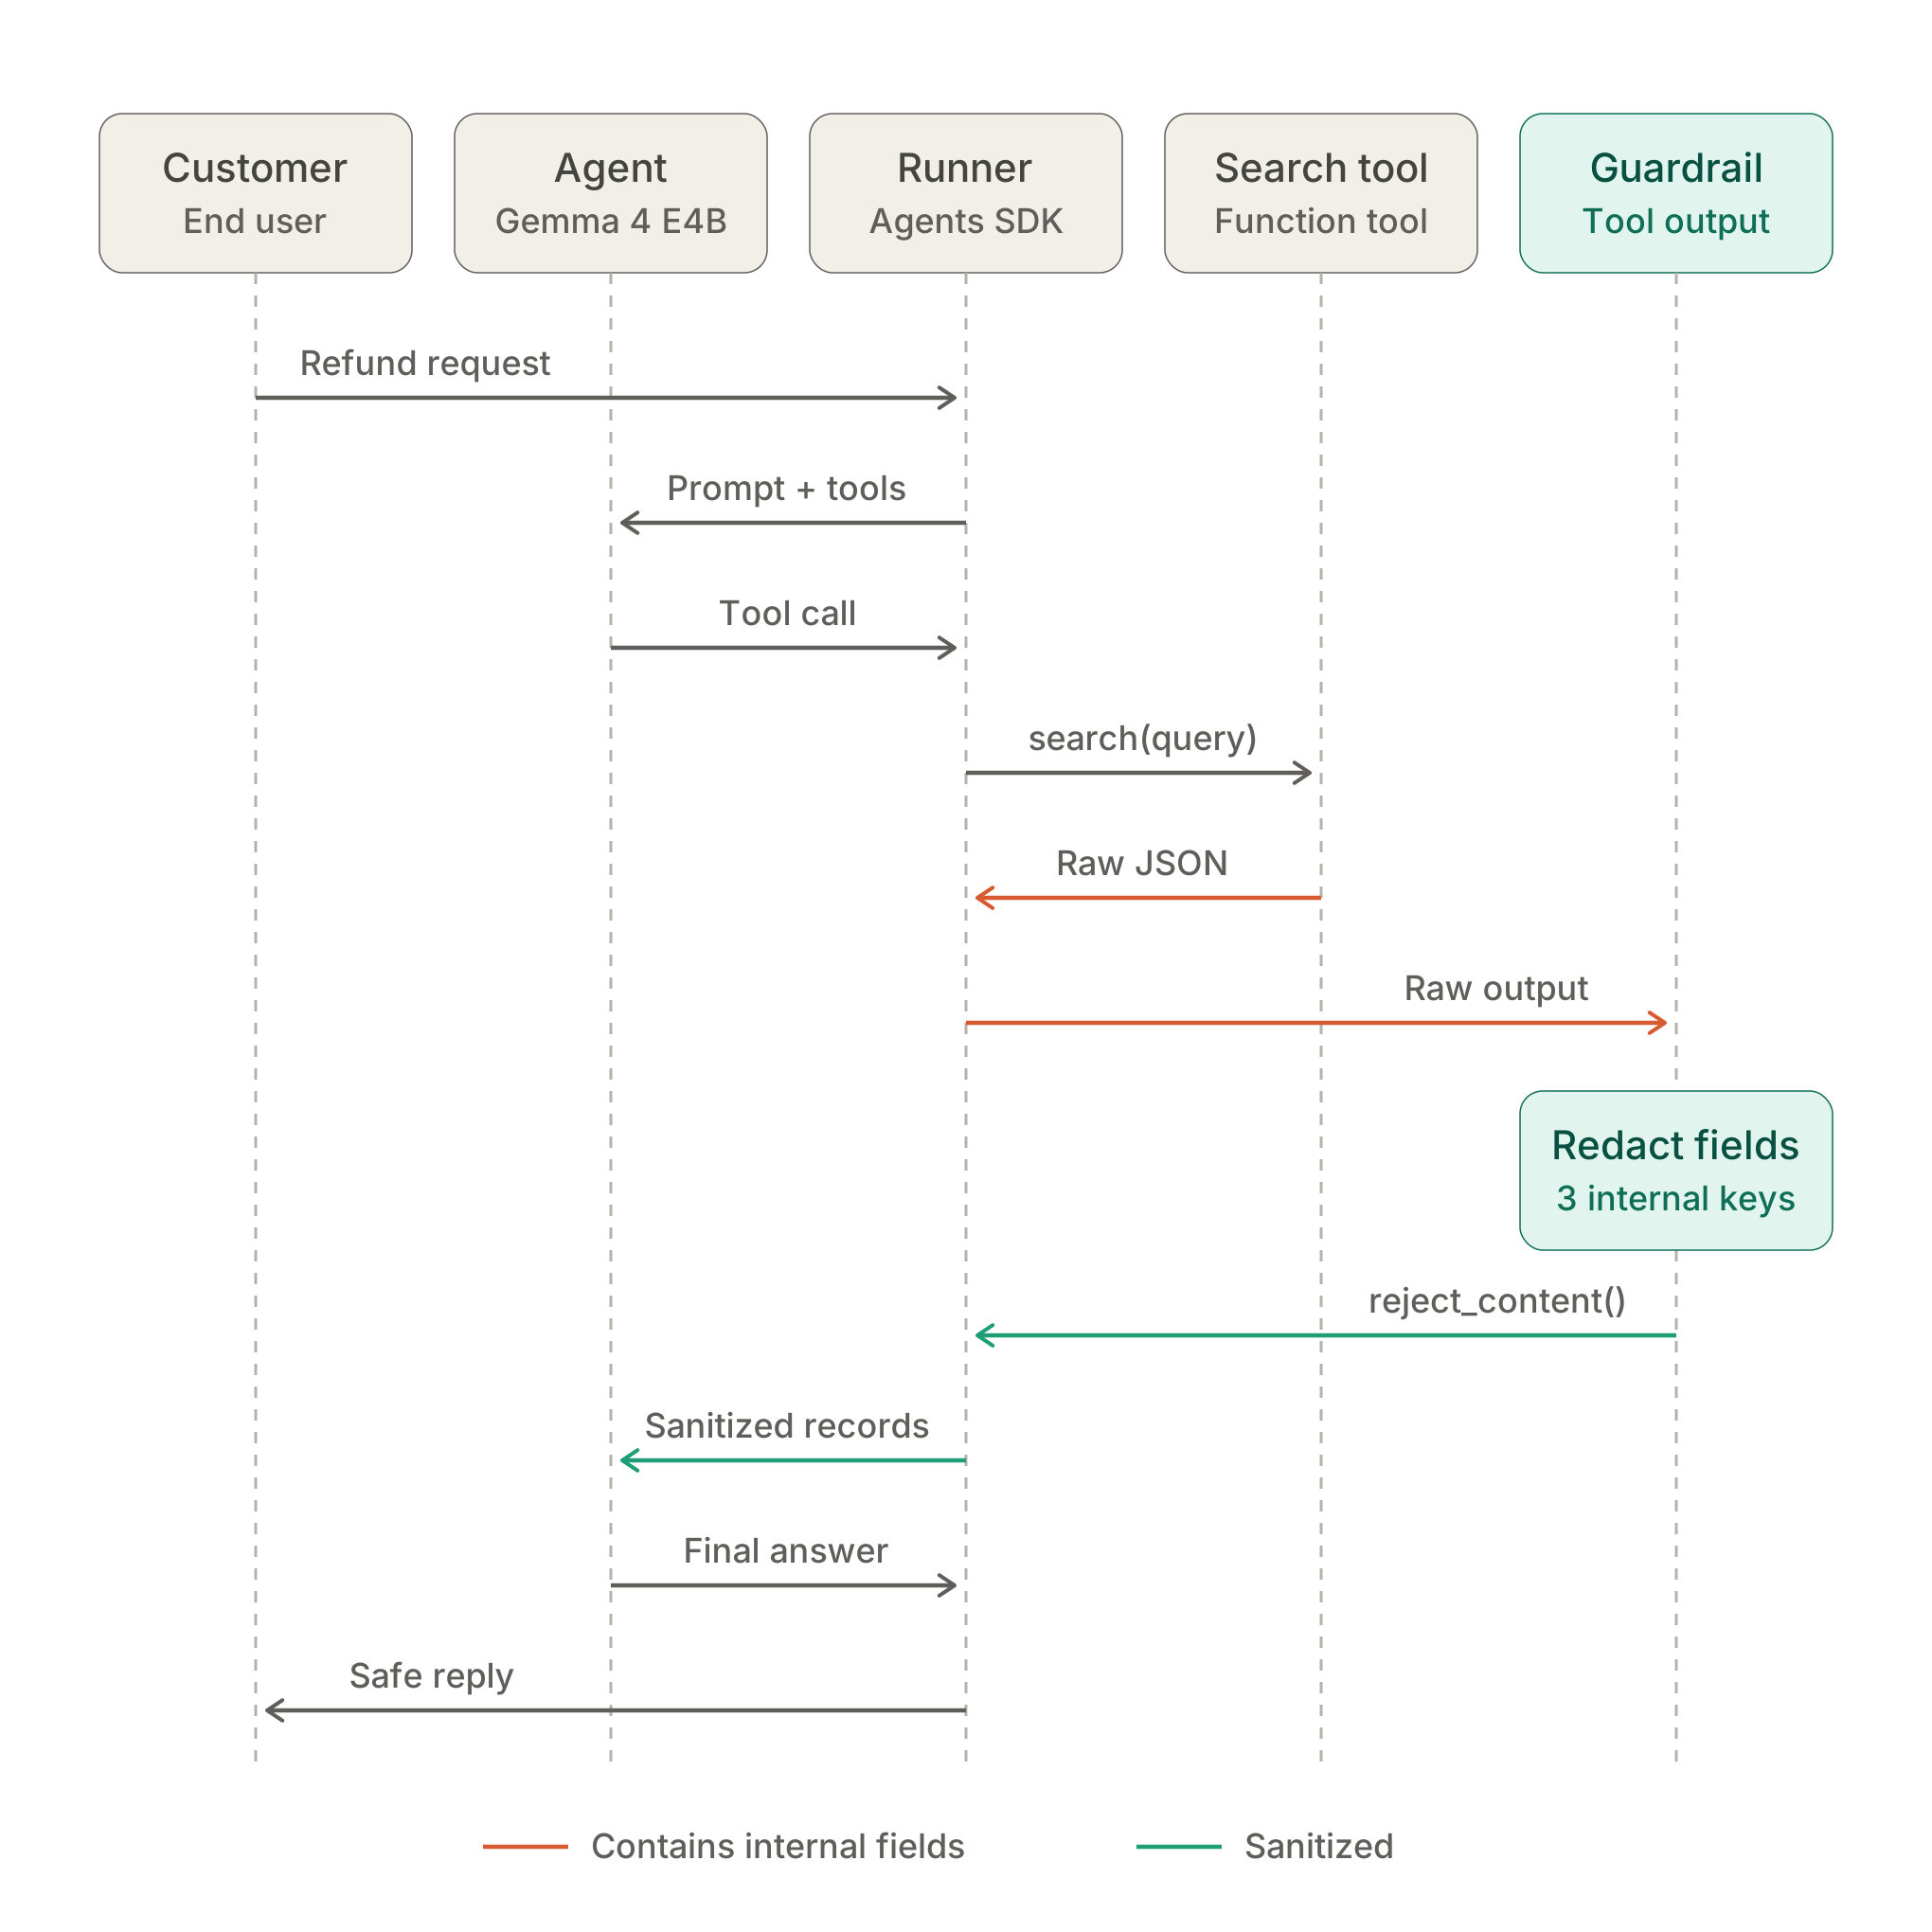
A hands-on guide with Gemma 4, Ollama, and the OpenAI Agents SDK
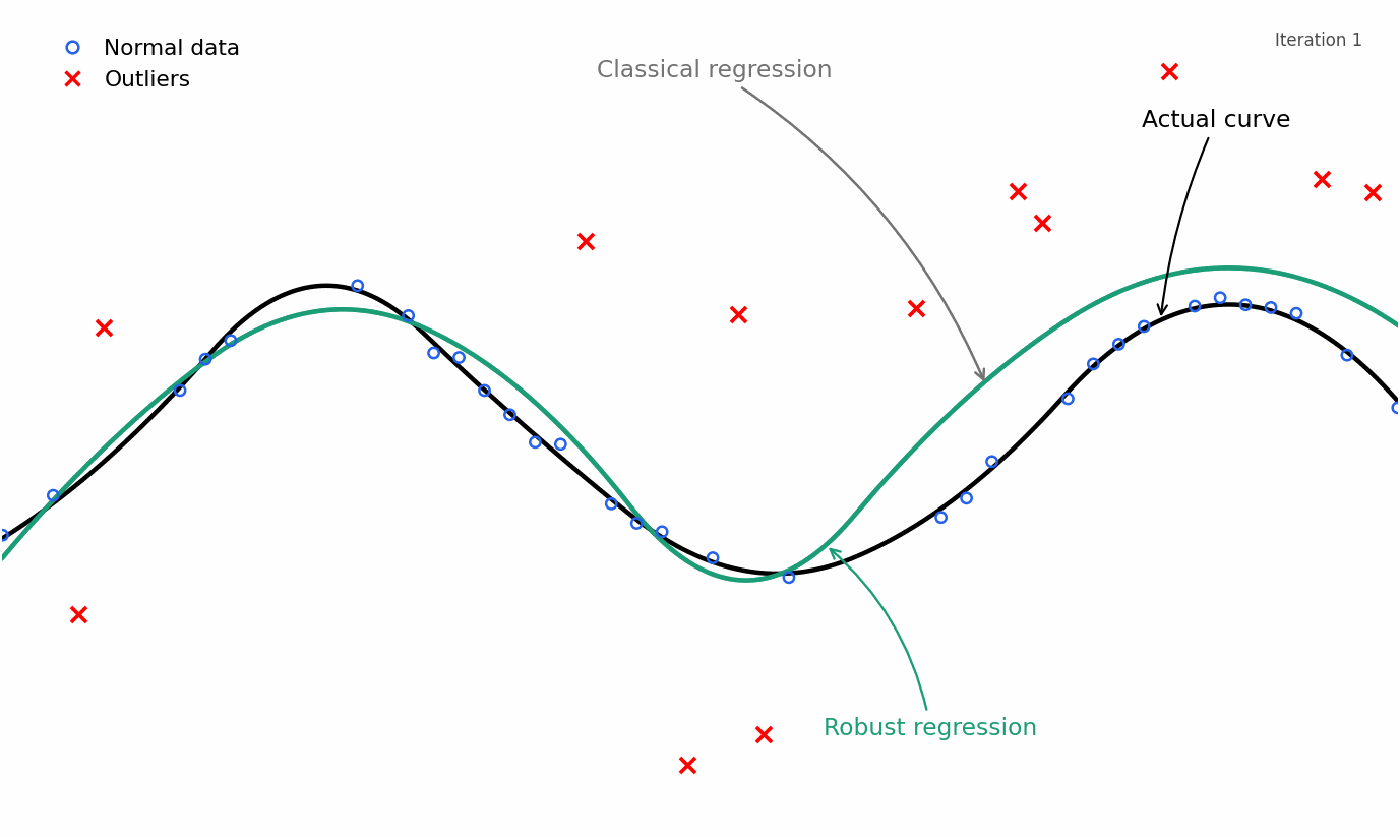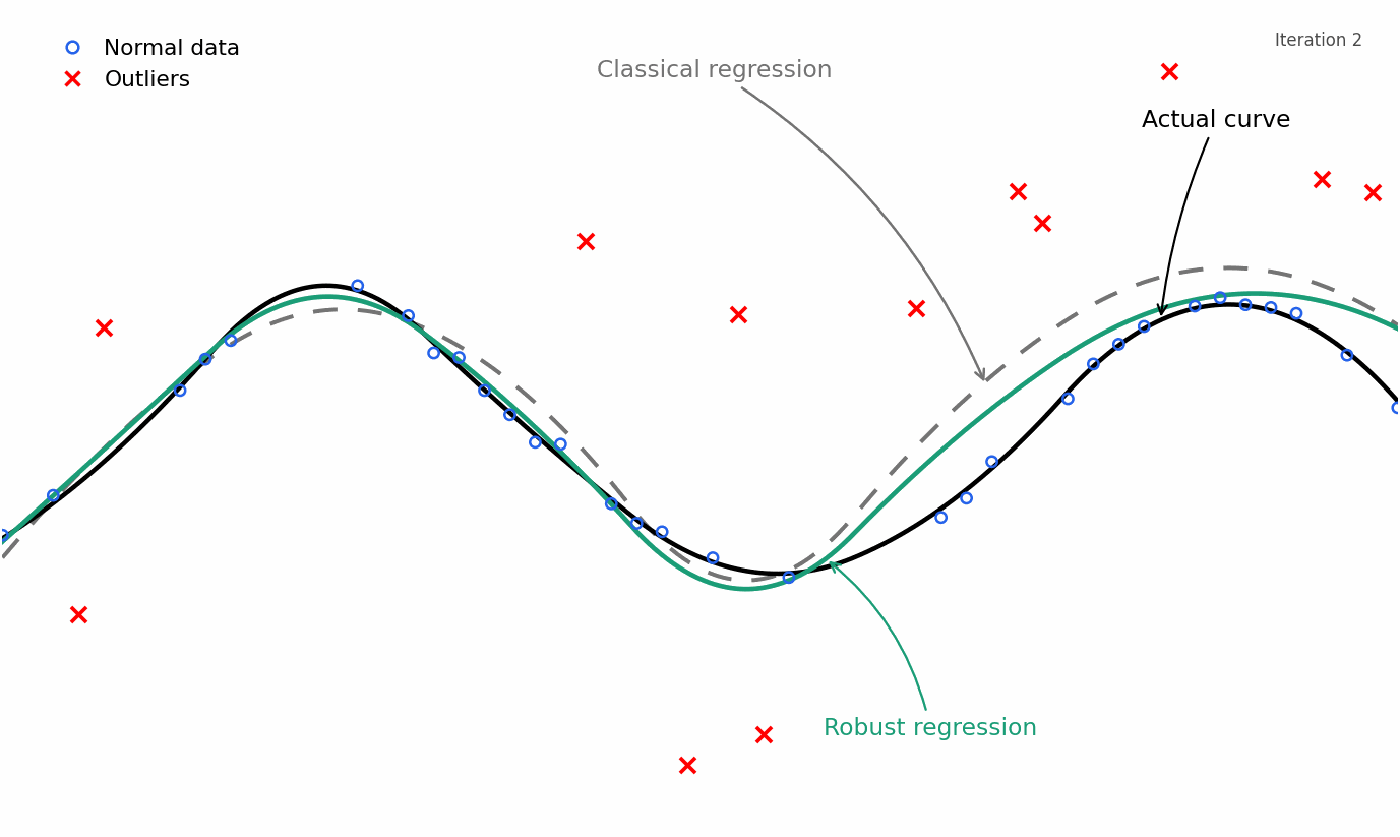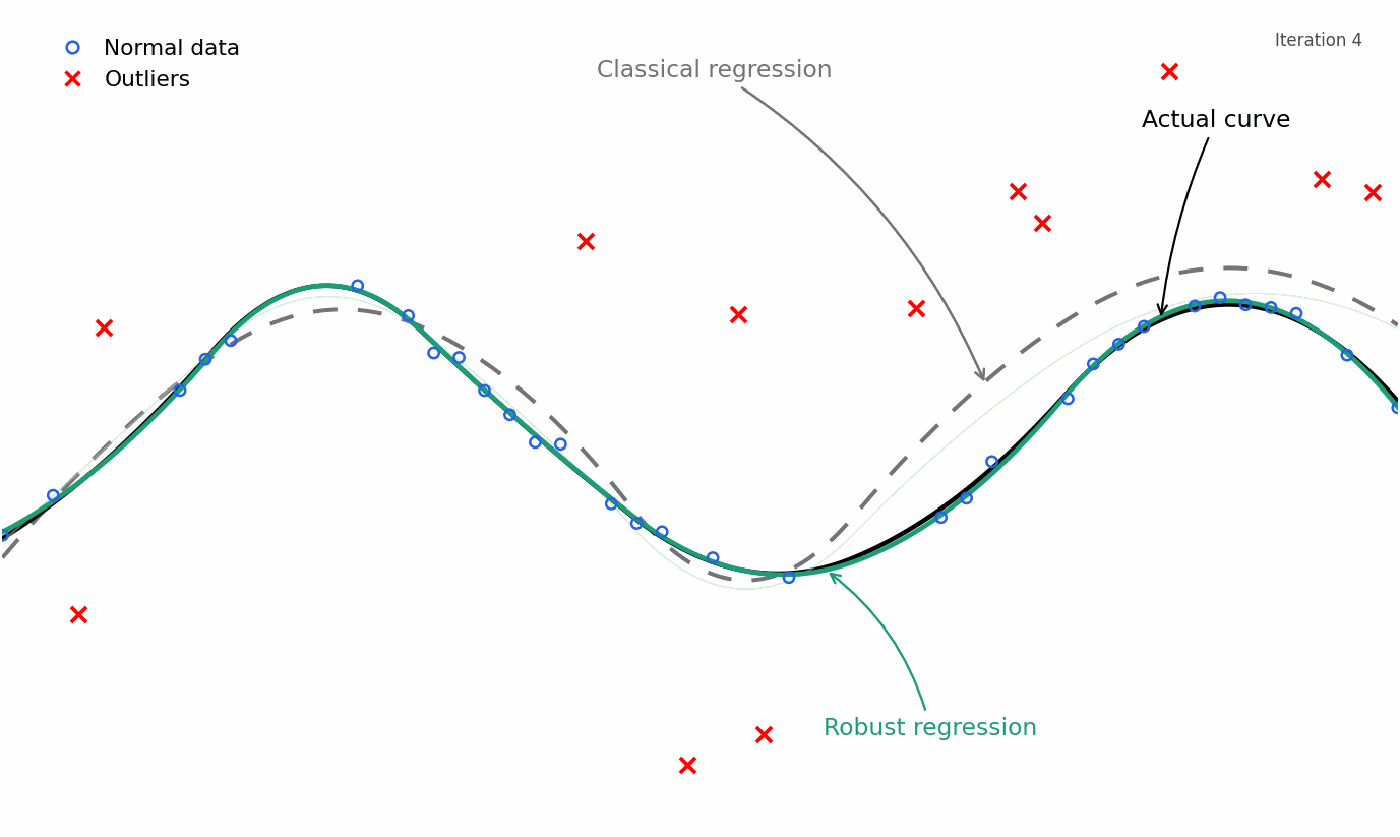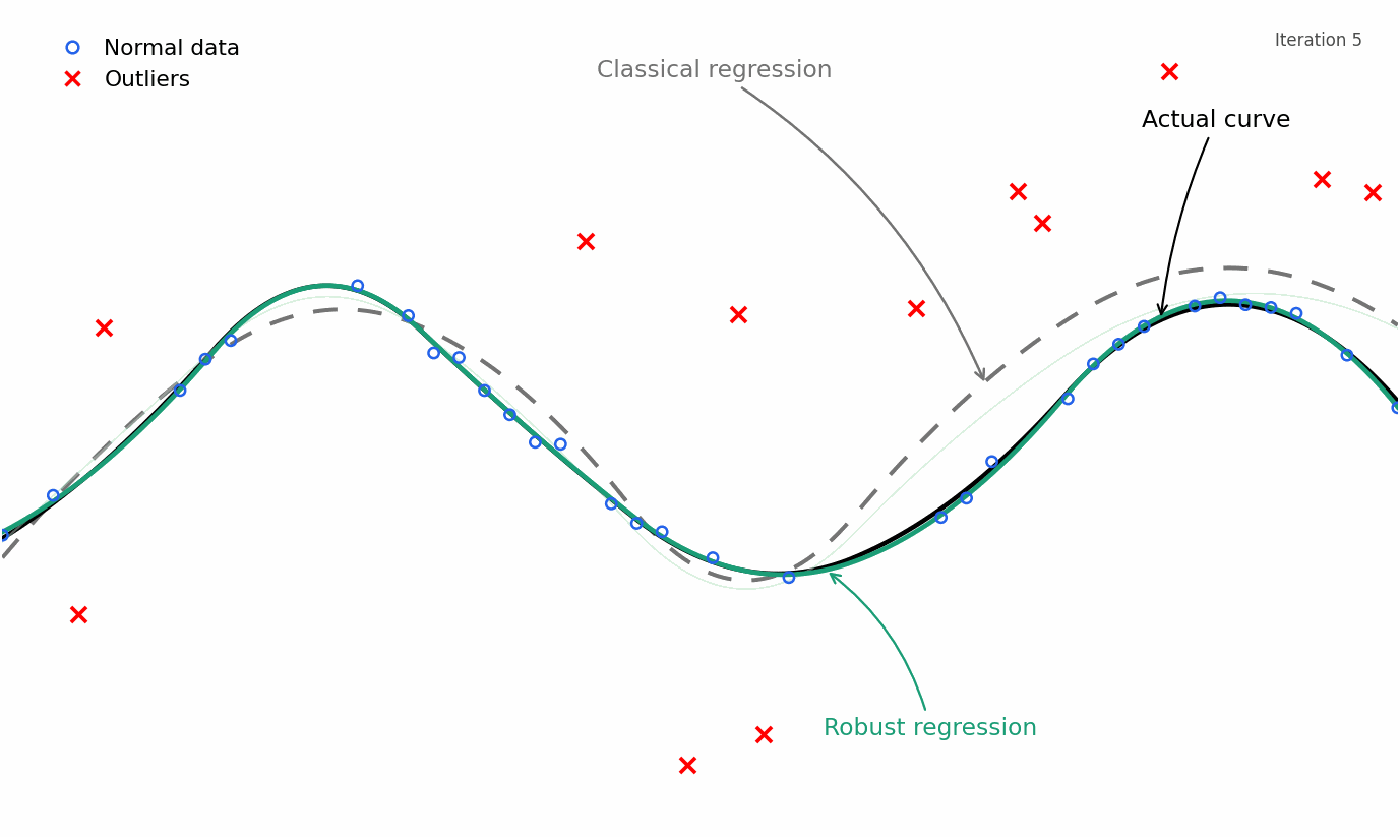
Robust Estimation Series: Building Accurate Curves with Polynomials and Splines With Spurious Data
The mathematics, intuition, interpretation, and practical use of higher-order moments.
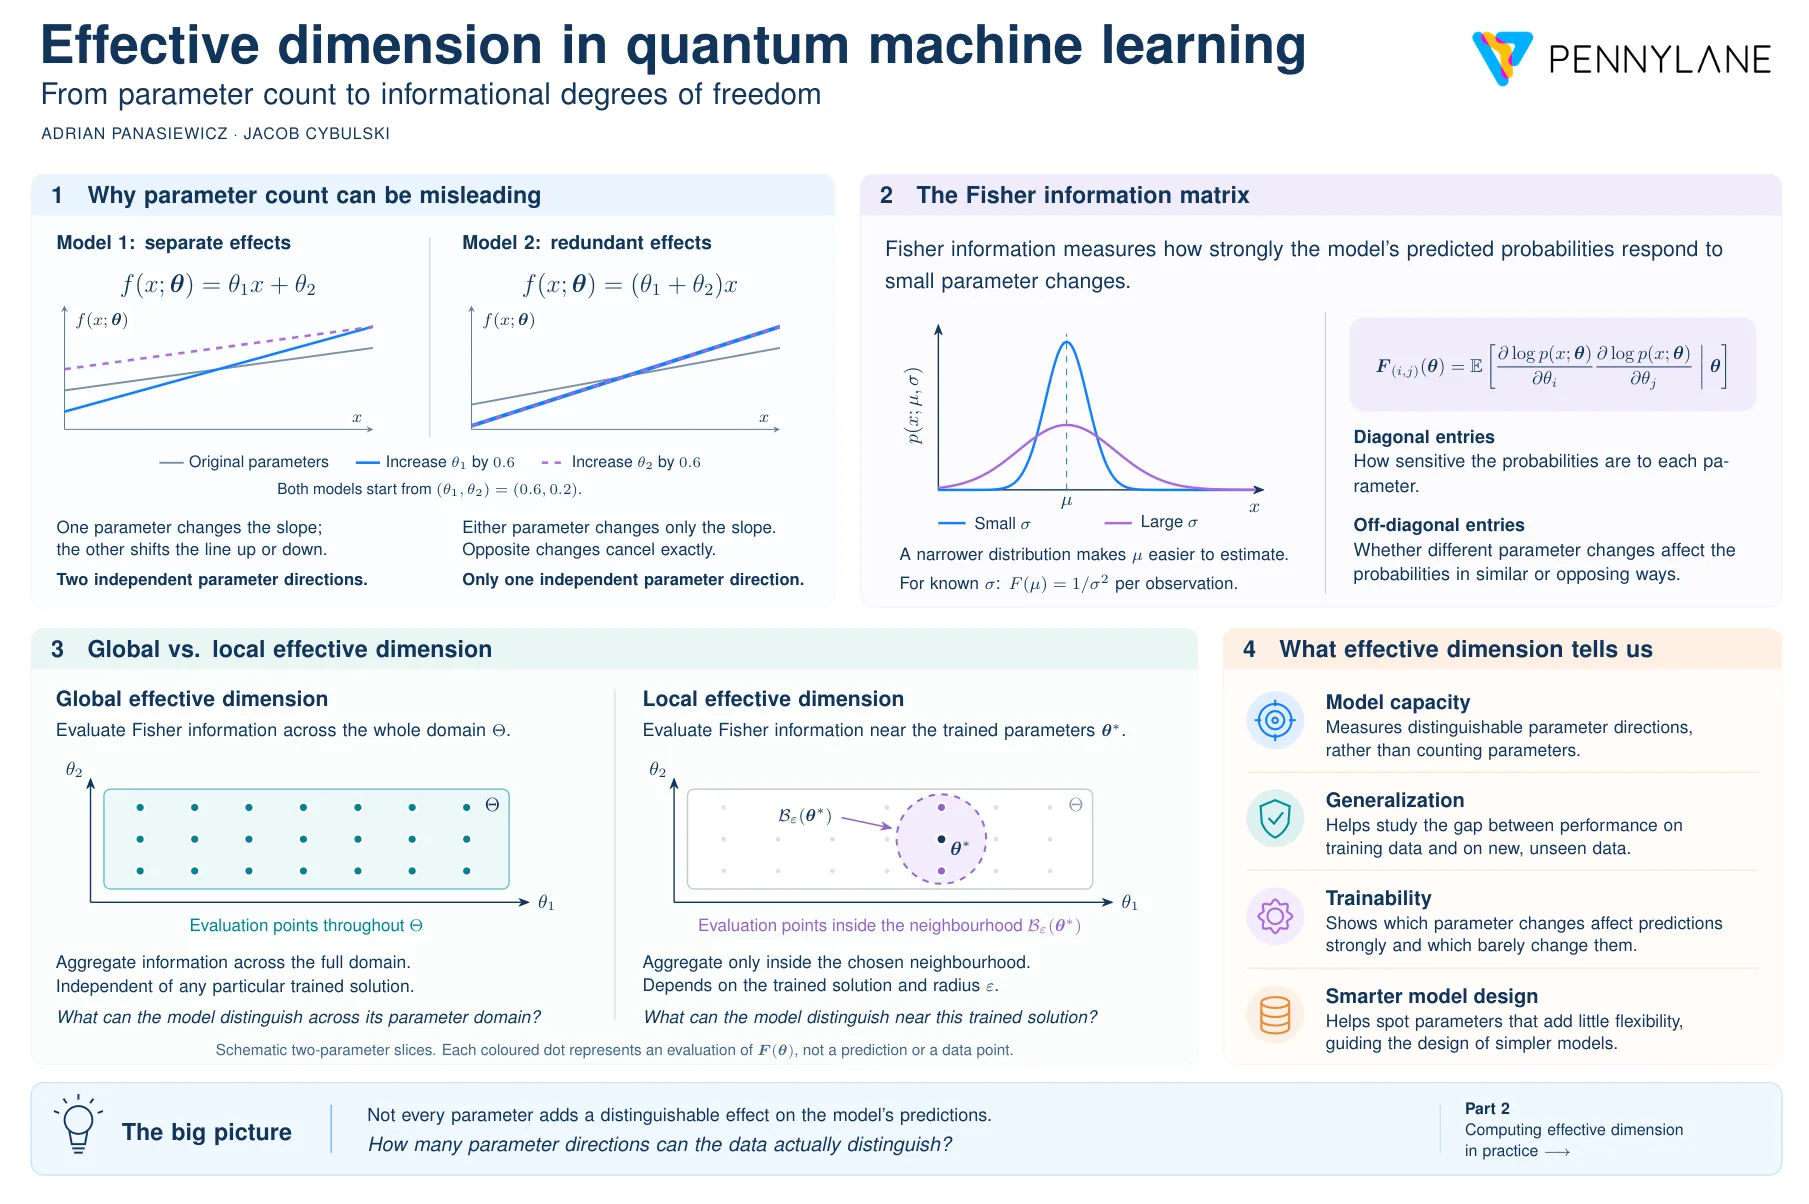
What does effective dimension reveal about redundancy, generalization, and trainability that parameter count, loss, and accuracy do not?
And how we can turn that feeling into insights
One benchmark says Claude Code used 33,000 tokens where Cursor used 188,000. Another says the exact reverse. Here is the field test that actually settles it for your team.
A hands-on guide with Gemma 4, Ollama, and the OpenAI Agents SDK
Robust Estimation Series: Building Accurate Curves with Polynomials and Splines With Spurious Data
The mathematics, intuition, interpretation, and practical use of higher-order moments.
What does effective dimension reveal about redundancy, generalization, and trainability that parameter count, loss, and accuracy do not?
Sorting through the good, bad, and ambiguous aspects of vibe coding
Don't miss our most-read and -shared stories of the past month
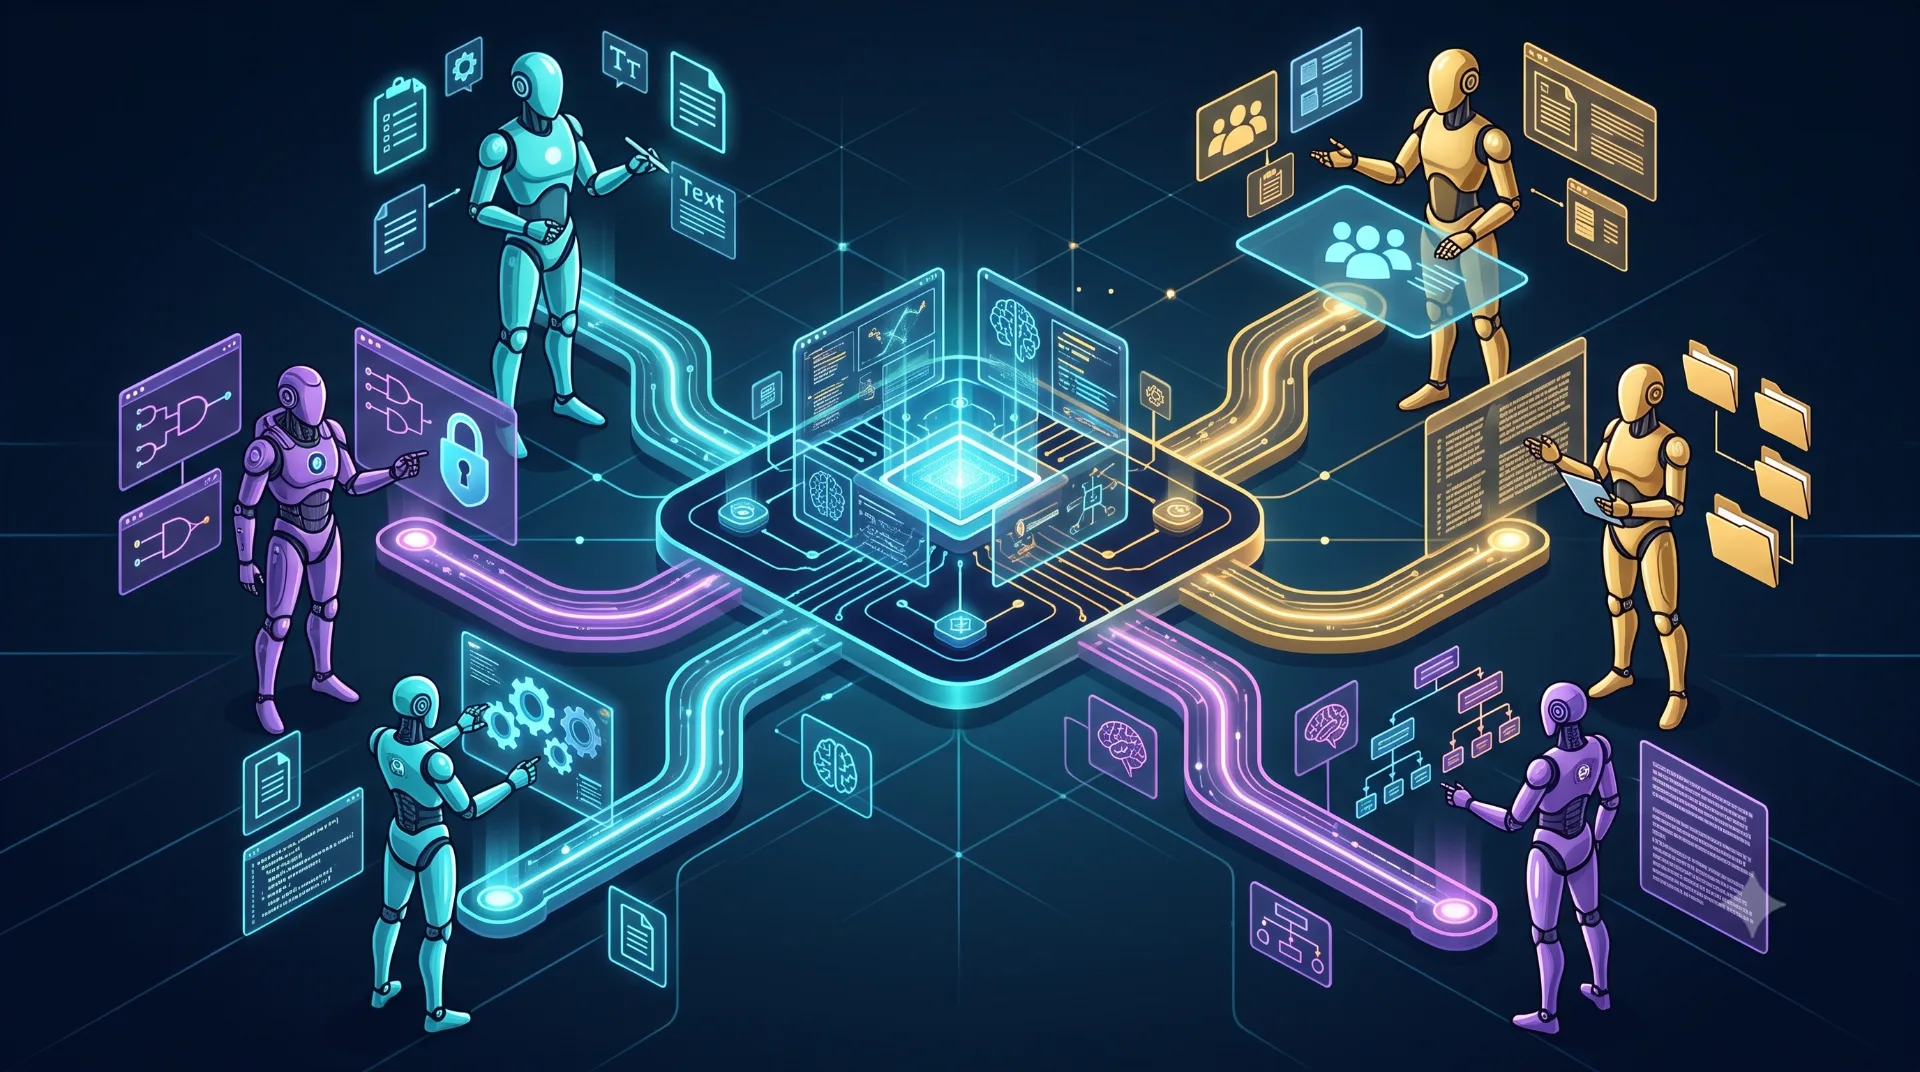
Beyond basic ReAct loops: six production-oriented architectures for building autonomous, reliable, and scalable LLM agents.
How statistical moments connect the mean, the variance, and higher powers of a distribution
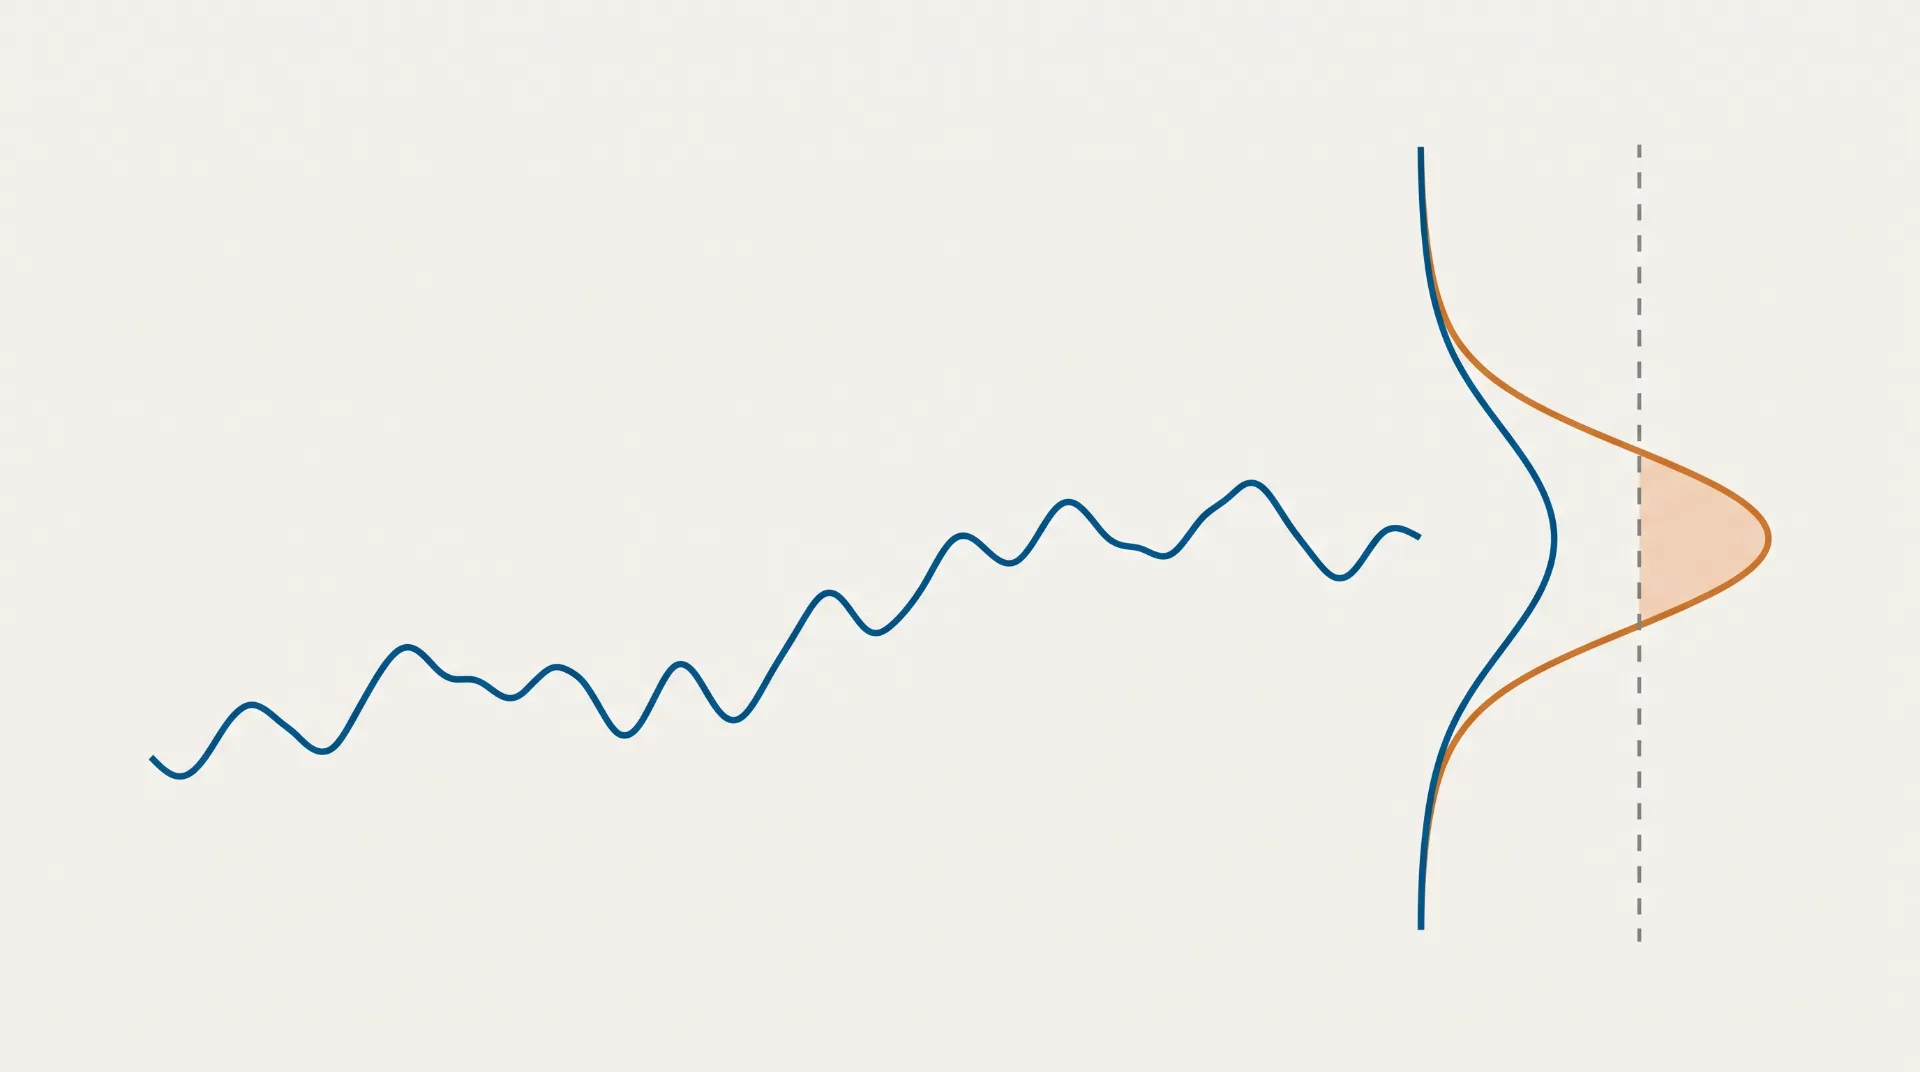
First in a series on probabilistic forecasting for physical signals. Next: what happens when you roll the forecast forward more than one step.
When Codex is the right shape for the problem, when Claude Code is, and how I split 5 specialist agents between them on dense AI capacity work.
Why the skill-inflation panic is aimed at the wrong thing, and what it costs to make agent knowledge a build artifact instead of a file.
A real Weave project that regression-tests three OpenAI models against the exact reply format your app depends on.