Each 5-minute case study pairs operational context, a problem statement, and documented code, so data scientists and non-coding planners learn together.
Each 5-minute case study pairs operational context, a problem statement, and documented code, so data scientists and non-coding planners learn together.
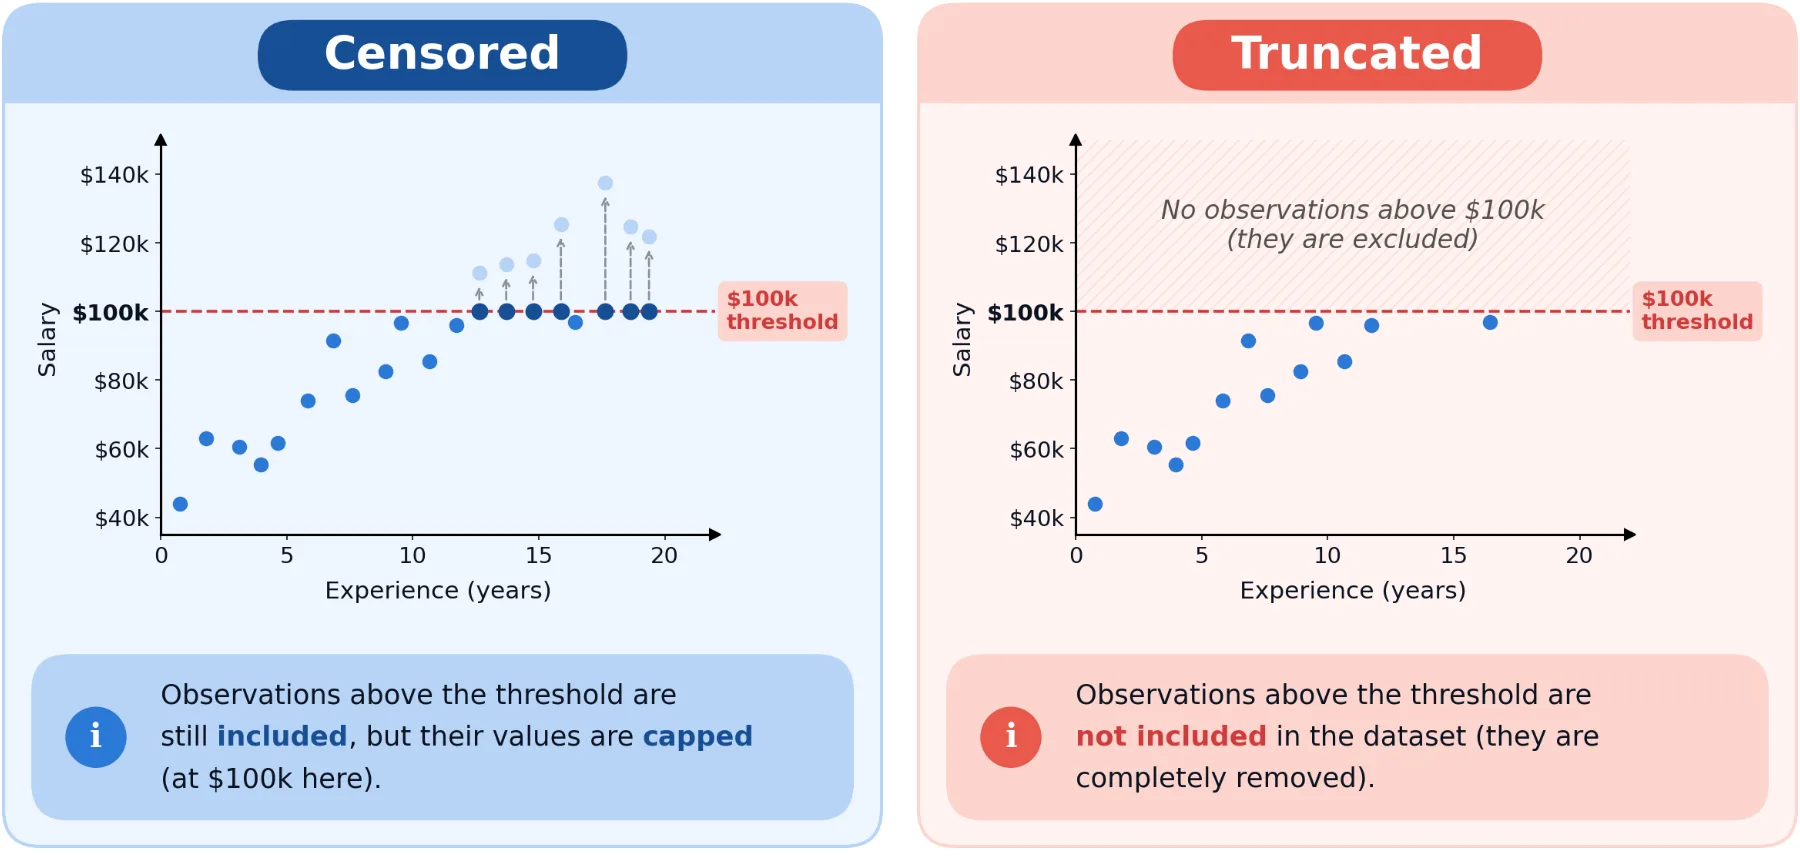
A simulated salary survey shows OLS shrinking a $5k-per-year effect to $3.2k, then recovers it with Tobit and truncated likelihoods built from scratch.
A 48-hour Capital Bikeshare experiment pits XGBoost, Ridge, SARIMA, and Prophet against simple baselines, with care for missing hours and leakage.
With a 0.9 confidence cutoff, Cloudflare's System One model handles the easy cases and routes the rest to a bigger, slower LLM like Luna.
Two years of interviewing master's students distilled into one logistic regression scoring model, from missing values and VIF to AUC and Gini.
AI Agents for Beginners, Part three: strict Pydantic arguments, a tool allowlist, read-only SQLite, a step cap, and confirmed writes, all verified by five pytest tests in 0.68s.
Exact uniform math and 100 synthetic Python runs show when to target 95% coverage and when asymmetric squared-error costs call for the expectile.
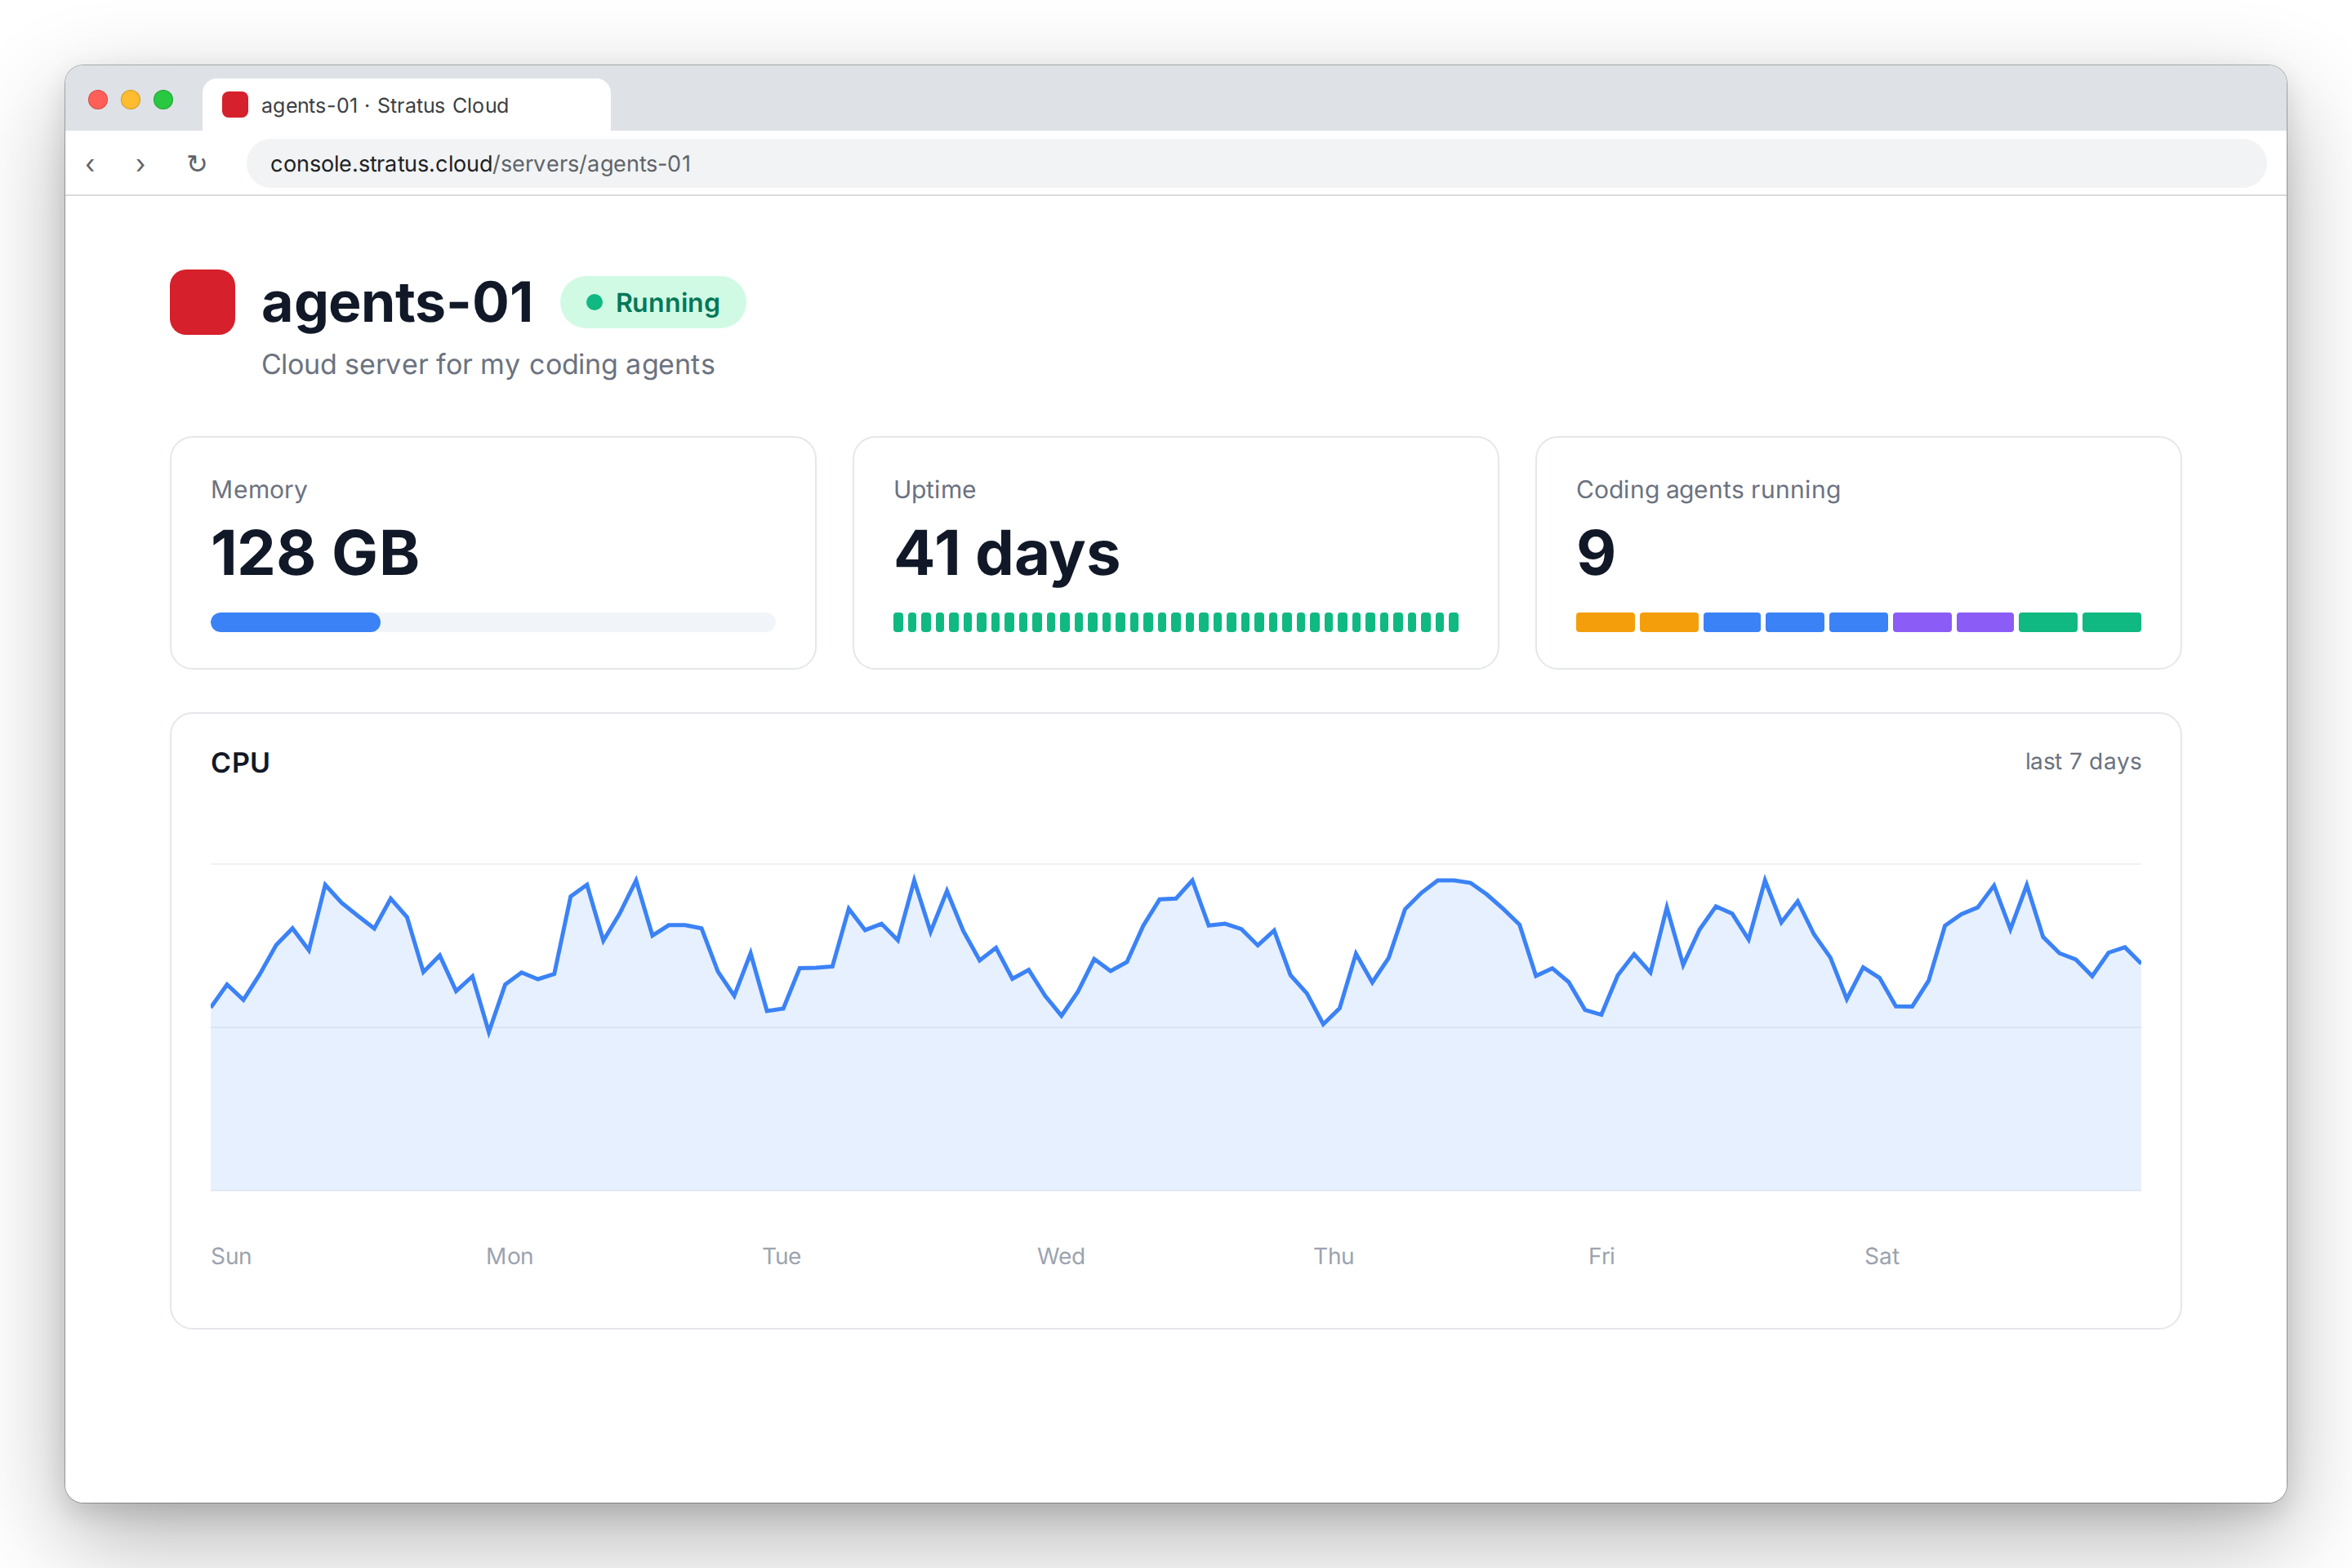
Two setups: flip Claude Code's cloud environment on for the quick path, or rent a server for full control.
Separate runtime oversight from human review: an autonomous supervisor handles reversible fixes, while humans approve high-impact changes.
Why grains, joins, filters, and tests need business translations, and how a four-step framework keeps stakeholders from misreading metric changes.
Managing Security When You’re Deploying AI, Part 1: Compromised credentials, salaries inferred from budgets, and doctored documents show why agents need permission checks before the model ever sees the data.
A simulated salary survey shows OLS shrinking a $5k-per-year effect to $3.2k, then recovers it with Tobit and truncated likelihoods built from scratch.
A 48-hour Capital Bikeshare experiment pits XGBoost, Ridge, SARIMA, and Prophet against simple baselines, with care for missing hours and leakage.
With a 0.9 confidence cutoff, Cloudflare's System One model handles the easy cases and routes the rest to a bigger, slower LLM like Luna.
Separate runtime oversight from human review: an autonomous supervisor handles reversible fixes, while humans approve high-impact changes.
Why grains, joins, filters, and tests need business translations, and how a four-step framework keeps stakeholders from misreading metric changes.
Managing Security When You’re Deploying AI, Part 1: Compromised credentials, salaries inferred from budgets, and doctored documents show why agents need permission checks before the model ever sees the data.
Sorting through the good, bad, and ambiguous aspects of vibe coding
Don't miss our most-read and -shared stories of the past month
Beyond basic ReAct loops: six production-oriented architectures for building autonomous, reliable, and scalable LLM agents.
How statistical moments connect the mean, the variance, and higher powers of a distribution
First in a series on probabilistic forecasting for physical signals. Next: what happens when you roll the forecast forward more than one step.
When Codex is the right shape for the problem, when Claude Code is, and how I split 5 specialist agents between them on dense AI capacity work.
Why the skill-inflation panic is aimed at the wrong thing, and what it costs to make agent knowledge a build artifact instead of a file.
A real Weave project that regression-tests three OpenAI models against the exact reply format your app depends on.