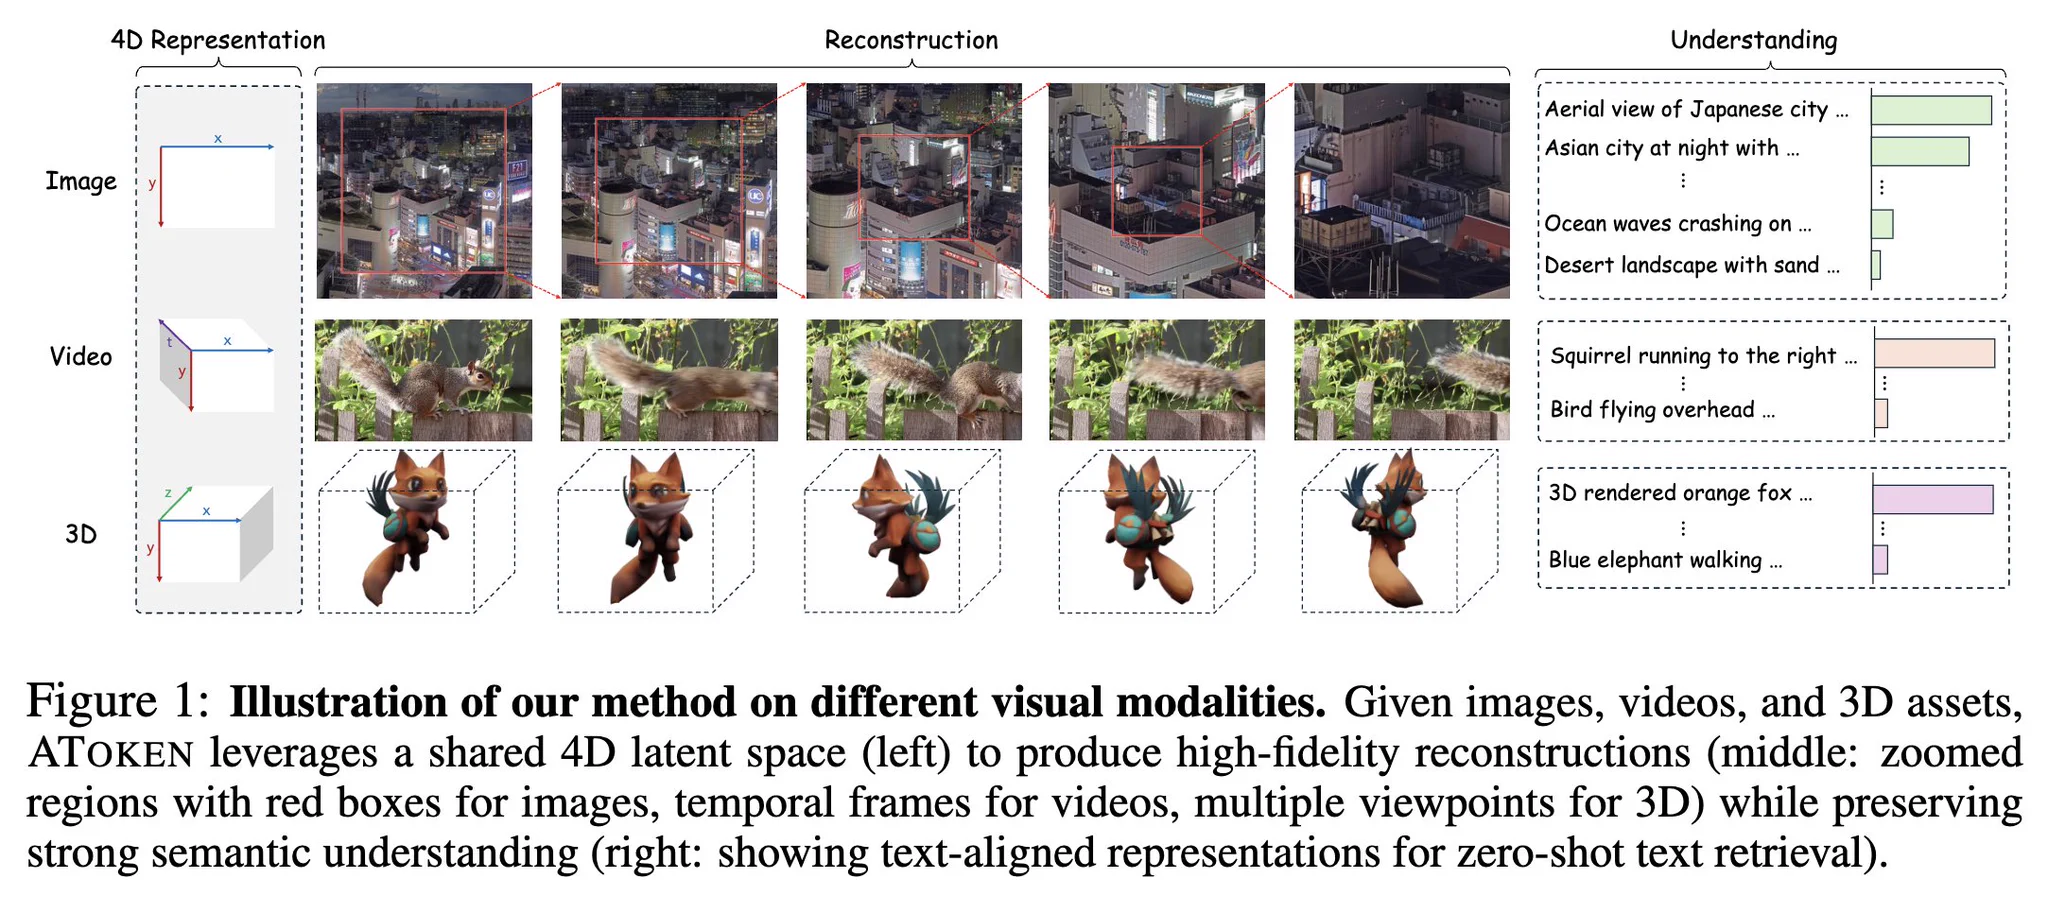
Apple presents AToken: A unified visual tokenizer
• First tokenizer unifying images, videos & 3D
• Shared 4D latent space (preserves both reconstruction & semantics)
• Strong across gen & understanding tasks (ImageNet 82.2%, MSRVTT 32.6%, 3D acc 90.9%)
Today we are releasing JST-2, the world's first full-stack physics-native world foundation model.
Many world models learn in pixel/video space. We went back to first principles and built the entire model stack in 3D.
Generate a 3D scene in seconds and expand it in real
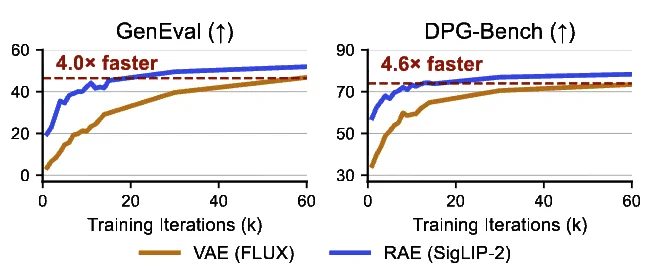
Just checking the paper, I realize the figure is very similar. It is actually one of the GitHub Issue I post earlier about missing details in RAE (github.com/bytetriper/RAE…). Huge improvement! Congrats with the team and nicely done!
> "rae can’t scale"
> "rae can’t generalize past imagenet"
> "rae can’t do details"
> instead of arguing online
> students put heads down
> try it at real t2i scale
> results come back
> look extremely bullish
> shoutout to peter, boyang, austin
> and everyone who shipped
>
Last October, we introduced Representation Autoencoders (RAE), showing that training diffusion on frozen semantic representations works and outperforms VAEs on ImageNet.
We received many questions: Can this scale to complex settings like T2I? Do the advantages hold?
The answer is
Huge congrats to the VQA team on winning the Everingham Prize! 🚀
10 years ago, before I started my PHD, Devi asked me to code some simple baselines for VQA. I said no the first time🤦♂️
She asked again. I said yes, worked on the method part of the paper, and accidentally spent
Thank you to the award committee and the broader vision community for the recognition. After all these (21!) years and so many conferences across sub-disciplines in AI, the vision community continues to feel like home.
What makes this extra special is that the original VQA
Checked out Apple’s latest Flagship project! While focused on AToken, I admired the compute and resources on this flagship project, and the result is also amazing🎉
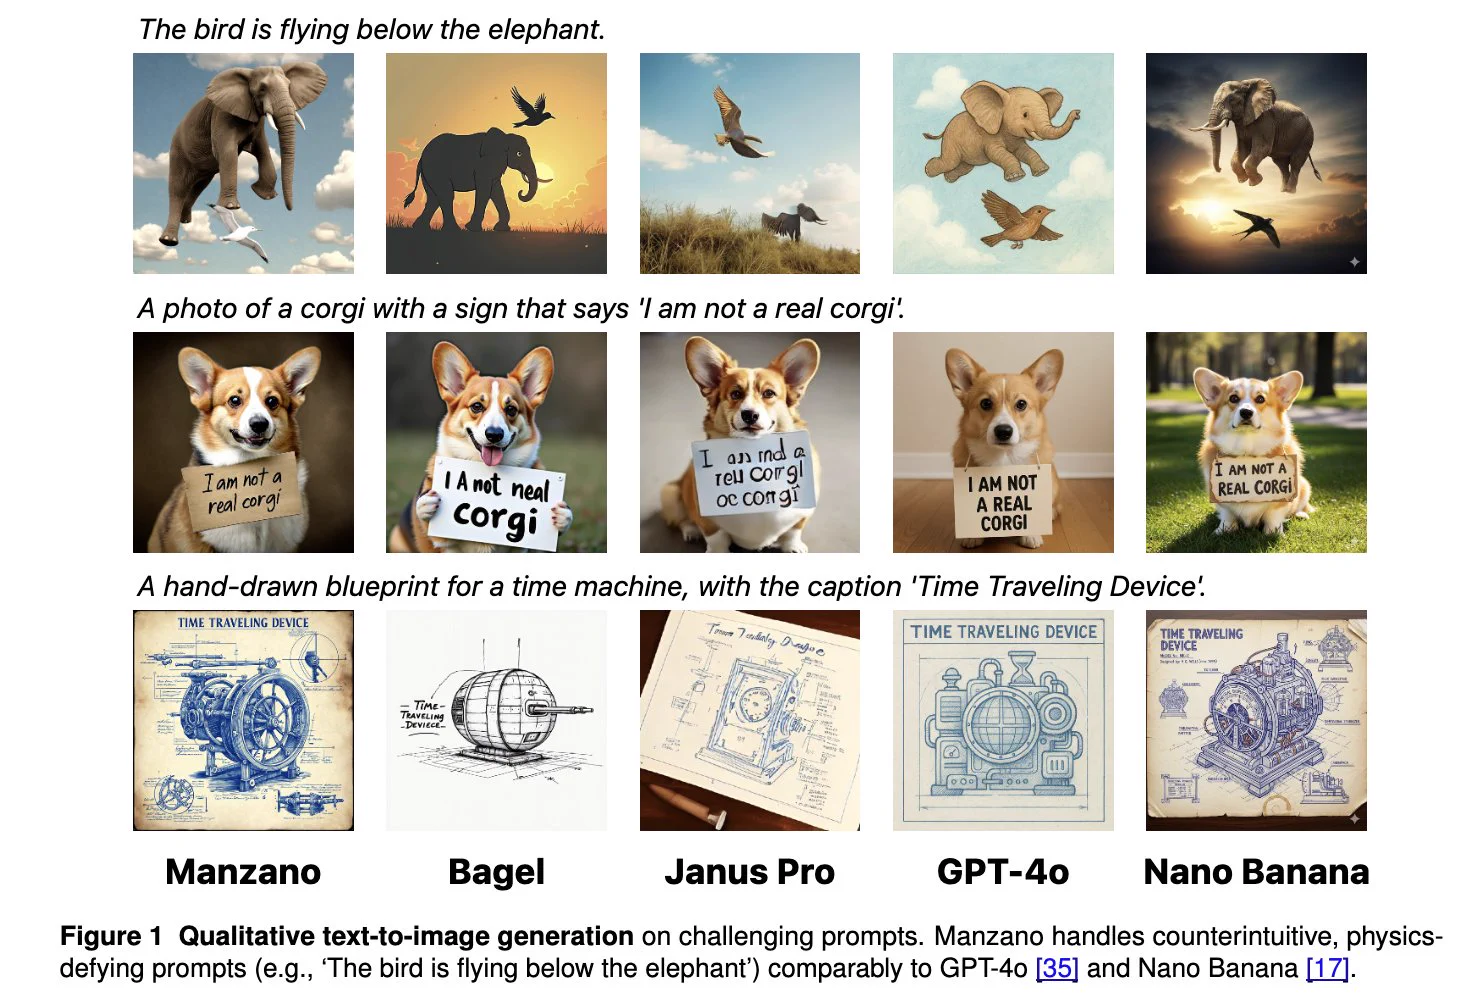
Apple presents Manzano: Simple & scalable unified multimodal LLM
• Hybrid vision tokenizer (continuous ↔ discrete) cuts task conflict
• SOTA on text-rich benchmarks, competitive in gen vs GPT-4o/Nano Banana
• One model for both understanding & generation
• Joint recipe: