One Jev request, three scores: a policy label, a rubric level, and the probability the reply asks for a password, all recorded in Logfire.
Modeled cost of 1M evaluated replies: $62, vs $4,542 with Braintrust before data charges.
Blogpost
@e2b is now a native sandbox provider in Pydantic AI. One capability in the list, and the agent's shell runs in a microVM instead of on your laptop.
Pause it between runs. Kill the worker and recover in the same sandbox.
Mad plot twist - what if Monty could run JS and TS code, and even run and render React components!?
Just an experiment for now, but it works amazingly well.
This would be especially useful if you want agents to generate UI safely. Feedback welcome.
github.com/pydantic/monty…
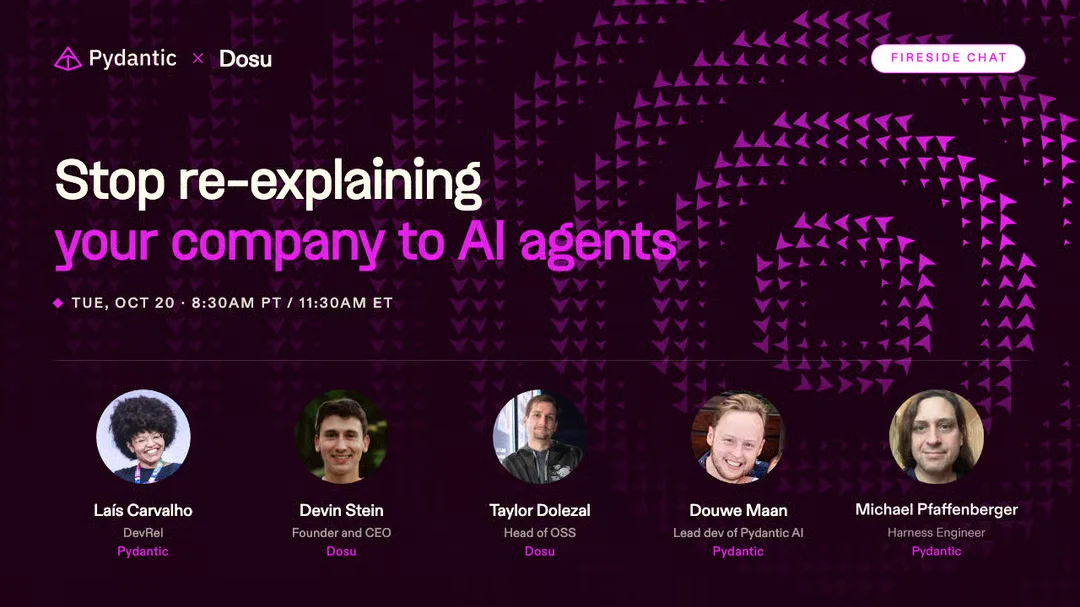
Last call: Tomorrow our engineers sit down with @dosu_ai on keeping internal agents’ company knowledge current:
- How to evaluate an internal agent
- When a person should review its work
- What agents should remember, and memory drift
Oct 20 at 8:30am PT/11:30am ET.
Register