Preserved thinking
Preserved thinking lets a model use a thinking block from an earlier turn only if that model or an earlier one produced it and nothing before the block has changed.
Preserved thinking is a property of newer Claude models that guards against distillation. It decides whether the model can use a thinking block that you send back from an earlier turn. Starting with Claude Fable 5.1, when a thinking or redacted_thinking block comes back in a request, the API checks the block's signature for two things:
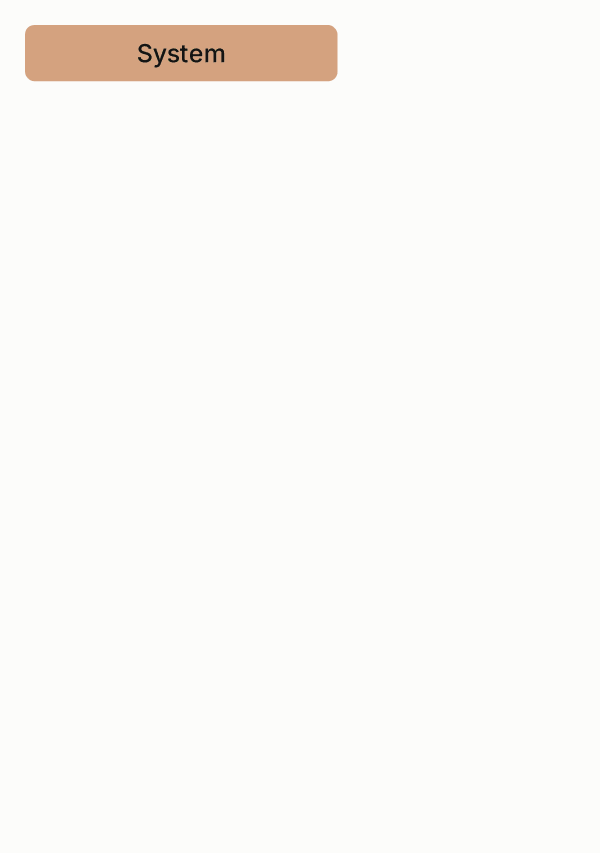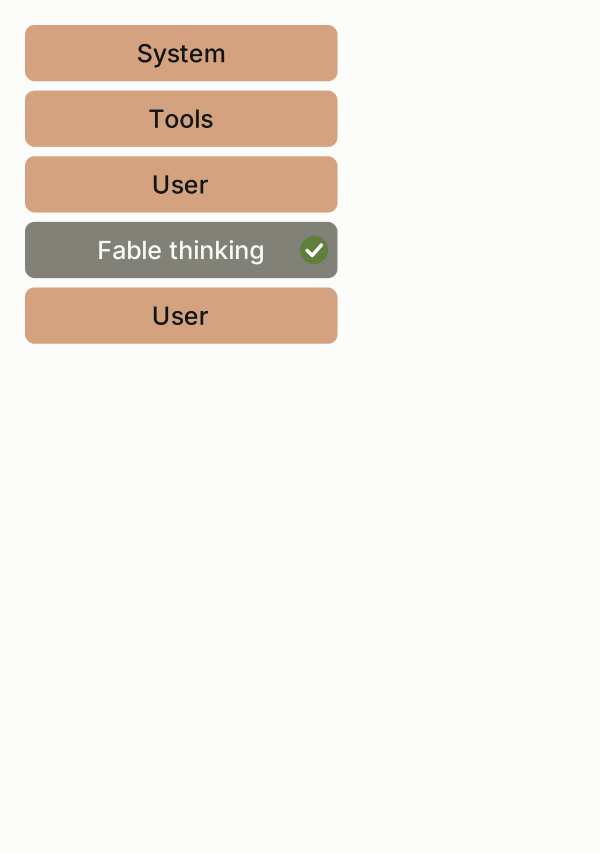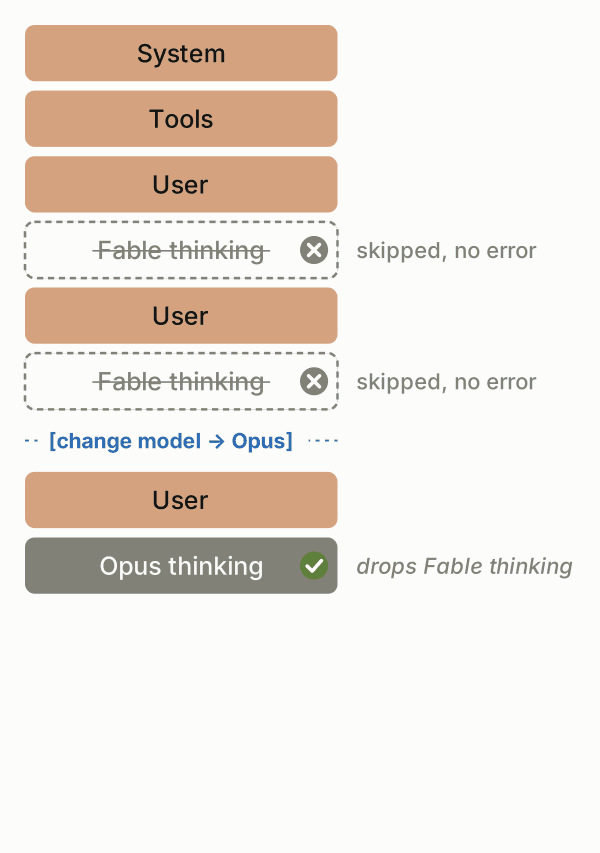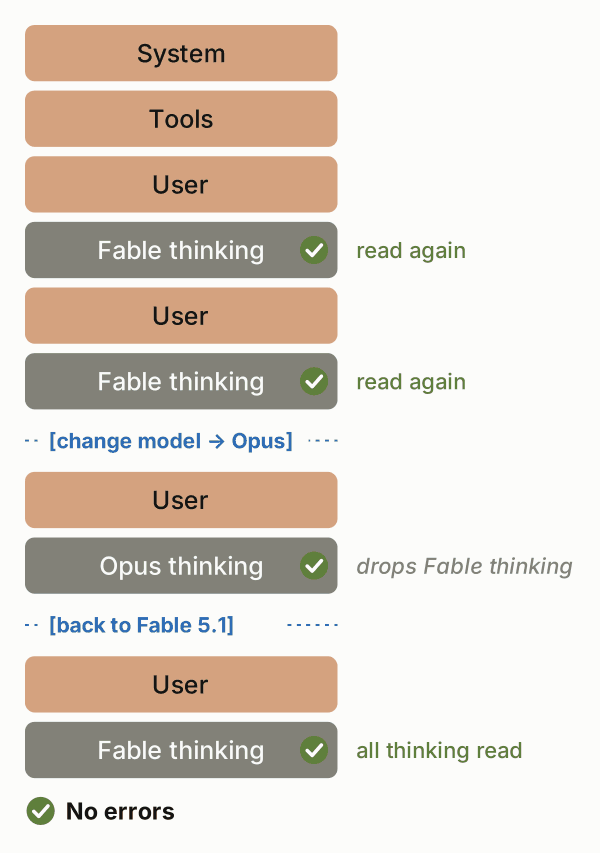
- The model is the one that produced the block, or a newer one. A model reads its own thinking blocks and those of earlier models. Claude Fable 5.1 reads blocks from Claude Opus 5, but Claude Opus 5 can't read blocks from Claude Fable 5.1. If the current model can't read a block, the API drops it from that request without an error. See Switching models mid-conversation.
- Nothing before the thinking block has changed. The top-level
systemprompt,tools, andmessagesbefore the block are its prefix. If the prefix differs from what you sent when the block was produced, that block and every later thinking block are invalid, and the API rejects the request with a 400 error or drops the invalid blocks, whichever you choose. See Keeping the prefix unchanged.
The model check applies to every account. The API enforces the prefix check by default for accounts created on or after August 31, 2026, 00:00 UTC. On older accounts, it enforces the prefix check only on requests that set thinking.block_binding.prefix_mismatch_behavior. Later models will enforce the prefix check for all accounts, so make your integration append-only now.
Who needs to change anything
Nothing changes for you if Claude Code, claude.ai, Claude Managed Agents, or the Claude Agent SDK builds your requests, or if your code keeps system and tools fixed for a session and only ever appends to messages. Claude Mythos 5.1 and models before Claude Fable 5.1 don't run the prefix check. If you never send thinking blocks back, the prefix check has nothing to reject, and the model gets none of its earlier reasoning.
Check your integration if, between two requests in one conversation, it does any of the following. Each item links to what to do instead:
- Rebuilds the
systemprompt: the date, a mode flag, re-read project instructions, or a plugin or MCP server that connects after the first turn - Re-renders the context in the first user message
- Clears or shortens old tool results, or re-encodes old images
- Summarizes or drops old turns on the client and keeps recent turns with their thinking
- Adds, removes, or edits entries in
tools - Adds a reminder to a user turn and removes or rewrites it later
- Drops some
thinkingblocks and keeps later ones, or removes them and later puts them back - Rebuilds a saved session from templates instead of replaying what it sent
On an older account, none of these produces an error unless the request sets prefix_mismatch_behavior, so a run with no errors on your own key doesn't show whether your code is affected. If people run your tool with their own API keys, those on newer accounts get the 400 error before you do. Set prefix_mismatch_behavior in your tests to see what they see.
Switching models mid-conversation
Claude Fable 5.1 and Claude Mythos 5.1 read thinking blocks produced by each other and by earlier Claude models. No earlier model reads thinking blocks from Claude Fable 5.1 or Claude Mythos 5.1.
- A conversation that moves up to Claude Fable 5.1 keeps its reasoning. The earlier model's thinking blocks stay readable, so the model thinks as usual from the first turn after the switch.
- A conversation that moves down to an earlier model loses Claude Fable 5.1's reasoning for that request. This happens when a router sends a turn to a cheaper model, after a classifier refusal fallback, or during a server-side fallback. The API removes the unreadable blocks before the prompt reaches the model. They aren't billed and don't count toward
input_tokens.
Keep sending the full history on every request, thinking blocks included, and let the API drop what the current model can't read. The API never edits your messages array, so the dropped blocks stay in your history. When the same history goes back to Claude Fable 5.1, its blocks are readable again, along with the earlier model's thinking. The reasoning is lost for good only if your client removes the blocks itself, for example a harness that strips thinking on a model switch or rebuilds the history from what each model used.
With the thinking-binding-controls-2026-08-01 beta header, the response lists each dropped block in a top-level input_transformations array with reason: "model_binding_mismatch":
{
  "input_transformations": [
    {
      "type": "thinking_dropped",
      "path": "messages.3.content.0",
      "reason": "model_binding_mismatch"
    }
  ]
}Without the header, the drop is silent. This entry isn't a bug in your integration, and prefix_mismatch_behavior has no effect on it: a block the current model can't read is always dropped.
Keeping the prefix unchanged
On Claude Fable 5.1, a thinking block stays valid only while everything you sent before it is unchanged on later requests. The checked prefix has three parts:
- The top-level
systemprompt - The set of
tools - Every
messagebefore the block
Note: With server-side compaction, the checked prefix starts at the most recent compaction block.
Request parameters outside those three fields, such as effort, max_tokens, output_config, tool_choice, and metadata, aren't part of the prefix check, and neither are cache_control markers. What counts as an edit has the full list.
Earlier thinking blocks aren't in the prefix, but each thinking block records which thinking block came before it, across turns. You can remove thinking blocks from the start of the history (oldest first), from the end, or all of them. What fails is a gap: the thinking blocks you keep must be an unbroken run of the original sequence, so removing one from the middle invalidates the thinking blocks after it. Once you remove a block, leave it out. Putting it back invalidates the thinking blocks produced while it was gone.
Keep system and tools fixed for the session and treat messages as append-only. The same discipline keeps the prefix stable for prompt caching: the edits that invalidate thinking are the edits that restart the cache.
What the API does with an invalid block
You choose with thinking.block_binding.prefix_mismatch_behavior:
"error"(the default): the API rejects the request with a 400invalid_request_errorthat names the first failing block."drop_block": the API drops each failing block and every thinking block after it, and the request succeeds. Dropped blocks aren't billed. The model answers that turn without using reasoning from dropped blocks, and the prompt cache restarts at the edit. The response lists each dropped block ininput_transformations(on themessage_startevent when streaming) withreason: "prefix_binding_mismatch".
"drop_block" keeps requests succeeding but doesn't fix the edit. Count the responses in each session whose input_transformations has a prefix_binding_mismatch entry, and alert on them. In the Message Batches API, an item that leaves the field unset drops failing blocks instead of erroring, so set "error" explicitly there if you want batch items to fail.
Both the field and the input_transformations array require the thinking-binding-controls-2026-08-01 beta header. Set the mismatch behavior and read input_transformations shows the request in each SDK.
The 400 message begins:
messages.1.content.0: Invalid `signature` in `thinking` block. The block is bound to a different conversation. Remove the block, or set `thinking.block_binding.prefix_mismatch_behavior` to "drop_block".If the request didn't send the beta header, the message continues:
That setting requires the `thinking-binding-controls-2026-08-01` value in the `anthropic-beta` header.It usually ends with a sentence naming what changed, for example that the system prompt or the tools list differs from when the block was created. Troubleshooting thinking describes what that sentence can name.
A tampered or undecryptable signature is a different failure. It always returns a 400 (Invalid `signature` in `thinking` block with no sentence about the conversation), and prefix_mismatch_behavior doesn't apply to it.
Handle the error in code
This is the 400 invalid_request_error shown earlier in this section. Don't resend the same body: it fails the same way every time. Retry once with the beta header and prefix_mismatch_behavior: "drop_block", and store that choice with the session so every later request sends it too, including after a restart. If you can't send the beta header, remove every thinking and redacted_thinking block from the history once, leave them out, and continue. Then fix the edit that caused the mismatch.
Set the mismatch behavior and read input_transformations
The thinking-binding-controls-2026-08-01 beta header adds:
- A top-level
input_transformationsarray on every response - A
block_bindingobject on thethinkingconfiguration, whose one field isprefix_mismatch_behavior
block_binding is accepted alongside thinking.type: "adaptive" and thinking.type: "enabled". Sending it without the beta header returns a 400 error whose message ends block_binding: Extra inputs are not permitted. Models that don't run the prefix check accept the object and report only model-check drops, so one request body works across models. The API reference calls the prefix check the conversation check.
The following request opts into dropping rather than rejecting. On a first turn there's nothing to replay, so input_transformations comes back empty:
client = anthropic.Anthropic()

response = client.beta.messages.create(
    model="claude-fable-5-1",
    max_tokens=16000,
    thinking={
        "type": "adaptive",
        "block_binding": {"prefix_mismatch_behavior": "drop_block"},
    },
    messages=[
        {
            "role": "user",
            "content": "What is the greatest common divisor of 1071 and 462?",
        }
    ],
    betas=["thinking-binding-controls-2026-08-01"],
)

for block in response.content:
    if block.type == "text":
        print(block.text)

print(f"Input transformations: {len(response.input_transformations or [])}")The greatest common divisor of 1071 and 462 is 21.
Input transformations: 0Under the beta header, every response from a thinking-capable model carries input_transformations. It's empty when nothing was dropped. Each entry has type: "thinking_dropped", the path of the dropped block (for example messages.1.content.0), and a reason of prefix_binding_mismatch or model_binding_mismatch (see Switching models mid-conversation). Ignore entries whose type or reason you don't recognize, because later checks add values.
When streaming, the array arrives on the message object in the message_start event. After a mid-stream server-side fallback, the final message_delta event carries it again with the serving model's entries. In a message batch, an item whose block fails the prefix check under an explicit "error" resolves as errored, and an item that leaves the field unset drops the failing blocks instead. The token counting endpoint runs the same prefix check and returns the same 400.
When the API enforces the check
The prefix check runs on Claude Fable 5.1 for new accounts.
- Accounts created on or after August 31, 2026, 00:00 UTC: the API checks Claude Fable 5.1 requests and applies
"error"unless you set"drop_block". The same definition of a new account applies to the Claude API and to cloud platforms. - Older accounts: the API checks requests that set
prefix_mismatch_behavior. This parameter opts a request in, so you can see what a new account sees without creating one. - Later models: every account, on every request.
To find out which group your account is in, take a Claude Fable 5.1 conversation that contains a thinking block, change something before that block, and send it to Claude Fable 5.1 without the beta header or the block_binding field. A 400 response that names the header means your account is enforced by default.
What counts as an edit
Each row compares two consecutive requests:
| Change between requests | Later thinking blocks |
|---|---|
| Append messages at the end | Valid |
Add a tool with defer_loading: true that nothing has referenced yet | Valid |
Remove thinking blocks from the start of the history, from the end, or all of them | Valid (the model loses that reasoning) |
Change any request parameter outside system, tools, and messages (effort, max_tokens, output_config, tool_choice, metadata, thinking.display, and so on) | Valid |
Add, move, or remove cache_control markers | Valid |
| A rotating signed URL that returns the same bytes | Valid |
| Server-side compaction or context editing removes or replaces content | Valid (the check compares what you sent, not the server's edited copy) |
| A cleared turn-scoped system message left in place | Valid |
Edit, reorder, or delete any earlier user, assistant, or system message | Invalid, except when the signed block from on-demand compaction replaces the messages it summarizes, under the conditions in Keep-tail compaction |
| Re-render the context you put in the first user message with a changed value | Invalid for every thinking block |
Clear or shorten an earlier tool_result, re-encode an earlier image, or change an earlier tool_use input | Invalid for every later thinking block |
| Add a text block to an earlier user turn, or remove one you added last time | Invalid |
Change the top-level system string or blocks | Invalid |
Add, remove, rename, or edit a tool in tools | Invalid |
Remove a thinking block from the middle of the history and keep later ones | Invalid for every later thinking block |
Put back a thinking block you removed on an earlier request | Invalid for thinking blocks produced while it was gone |
| An image or document URL that returns different bytes on the next request | Invalid |
| The same turn-scoped message deleted or reworded on a later request | Invalid |
Check whether your code edits the prefix
First, diff what you send. Capture the request bodies your integration sends over a few normal turns, including a compaction or a tool change. For each pair of consecutive requests, compare system, tools, and the messages they share. They should be identical up to the newly appended turns.
Then confirm against the API. Add the thinking-binding-controls-2026-08-01 beta header, set prefix_mismatch_behavior to "drop_block", and run a normal multi-turn session through your integration on . The following example runs two turns the way your integration should: messages only grows, each assistant turn goes back exactly as the API returned it, thinking blocks included, and block_binding is set on every request. After each turn it prints the number of thinking blocks in the response and the number of dropped blocks:
client = anthropic.Anthropic()

user_turns = [
    "How many positive integers below 500 have exactly 6 positive divisors?",
    "How many of those are odd?",
]

# messages grows across turns: each assistant turn goes back exactly as returned
messages = []
for user_turn in user_turns:
    messages.append({"role": "user", "content": user_turn})
    response = client.beta.messages.create(
        model="claude-fable-5-1",
        max_tokens=16000,
        thinking={
            "type": "adaptive",
            "block_binding": {"prefix_mismatch_behavior": "drop_block"},
        },
        messages=messages,
        betas=["thinking-binding-controls-2026-08-01"],
    )
    messages.append({"role": "assistant", "content": response.content})
    thinking_blocks = sum(block.type == "thinking" for block in response.content)
    dropped = len(response.input_transformations or [])
print(f"thinking blocks: {thinking_blocks}, dropped: {dropped}")thinking blocks: 1, dropped: 0
thinking blocks: 1, dropped: 0Neither turn drops a block because nothing earlier changed. Check that the first response contains a thinking block. With adaptive thinking, some responses have none. If no response in the session has one, there is nothing to check and the dropped count is 0 whatever you change, so run the example again.
Log input_transformations on every turn of your own integration. When the API drops a block, the entry looks like the following:
{
  "input_transformations": [
    {
      "type": "thinking_dropped",
      "path": "messages.1.content.0",
      "reason": "prefix_binding_mismatch"
    }
  ]
}- Empty on every turn of a session that contains
thinkingblocks: your integration keeps the prefix intact. reason: "prefix_binding_mismatch": something before the block atpathchanged since the previous request. Diffsystem,tools, andmessagesup to that turn to find it, or resend the request with"error": the 400 usually ends with a sentence naming what changed. Then find the matching replacement in Make changes without editing the prefix.reason: "model_binding_mismatch": the conversation moved to a model that can't read the earlier model's blocks. This isn't a prefix edit. See Switching models mid-conversation.
To see a failure on purpose, send a third turn from the earlier example and add a system prompt to that request only, so that it differs from the first two requests, which had none. With "drop_block", the dropped count is no longer 0: the response has one entry for each thinking block in the history, each with reason: "prefix_binding_mismatch". With "error", the request returns the 400 described in What the API does with an invalid block, and its last sentence names the system prompt. In the cURL and CLI tabs, remove the jq filter to see the error body. If the count is still 0, there was nothing to check: confirm that the model is , that the request sets block_binding, that the history you sent contains thinking blocks, and that the first two requests had no system prompt.
Two plain turns rarely show the problem. Run a session through each of the following, with "error" set so that a regression fails your CI:
- The first client-side compaction or trim
- A tool, plugin, or MCP server that connects after the first turn
- A mode or instruction change
- A long tool loop, if you add reminders or shorten old tool results
- A switch to another model and back
- A save, a restart, and a resume on a later date
Make changes without editing the prefix
Each common prefix edit has a replacement that gives the model the same information and leaves earlier bytes unchanged, so later thinking stays valid. Find the edit your code makes today in the first column:
| Instead of | Use | Beta header |
|---|---|---|
Rebuilding the top-level system prompt | A mid-conversation system message | None |
| Re-rendering the context in your first user message (environment, date, memory, project instructions) on each request | Render it once and resend it unchanged. When something changes, put the new version in the newest turn | None |
Clearing or shortening old tool_result content, or re-encoding old images, in place | Shorten a tool result or downscale an image before the first time you send it, not after. To clear old results later, trim context on the server with clear_tool_uses_20250919 | context-management-2025-06-27 |
| Injecting a reminder and deleting it on the next request | A turn-scoped system message (clear_at: "next_user_message") | mid-conversation-system-clear-at-2026-08-21 |
Adding or removing entries in tools | tool_addition and tool_removal blocks | mid-conversation-tool-changes-2026-07-01 |
Changing top-level output_config.effort (restarts the cache, doesn't affect thinking) | A per-message output_config | mid-conversation-output-config-2026-07-01 |
| Dropping or summarizing old turns on the client | On-demand compaction to keep the recent turns with their thinking, other server-side compaction or context editing, or client-side compaction that keeps no stale thinking | compact-2026-09-04 (not on Amazon Bedrock or Google Cloud) |
| An image or document URL whose bytes change between requests | A file_id from the Files API, or base64 | None |
All of these assume you send assistant turns back exactly as returned. Mid-conversation system messages, turn-scoped system messages, and tool changes aren't available on every model: Mid-conversation system messages and tool changes lists the models that accept them. If your code serves several models, keep editing the top-level system prompt for the models that don't accept them.
To use several betas in one request, combine the values in one anthropic-beta header. Beta names are the same on Amazon Bedrock and Google Cloud wherever the beta is available there (see Beta headers):
anthropic-beta: thinking-binding-controls-2026-08-01,mid-conversation-system-clear-at-2026-08-21,mid-conversation-tool-changes-2026-07-01Send assistant turns back exactly as returned
Store the content array from each response and send it back unchanged as the assistant turn: every block type, in the order received, including thinking blocks whose thinking field is empty. A serializer that drops unknown block types, drops empty fields, or reorders blocks edits the prefix for every later turn.
On Claude Fable 5.1, the thinking field is empty by default and the signature carries the reasoning, so a serializer that skips empty blocks removes thinking. If it removes all of them, nothing fails and the model loses its earlier reasoning on every turn. If you parse the stream yourself, keep the block even when no thinking text arrives: it opens, receives its signature in a signature_delta event, and closes. A block sent back with an empty signature fails.
Add instructions with a mid-conversation system message
Some harnesses rebuild the top-level system prompt on each request to carry the current time, a token budget, a mode flag, or newly discovered project context. That invalidates every thinking block in the conversation. Instead, freeze system at session start. When something changes, append a role: "system" message at the point in messages where the change becomes true:
{
  "role": "system",
  "content": "The user switched the workspace to read-only mode. Do not write files until told otherwise."
}The model treats this message with system-prompt authority, and everything before it stays unchanged. In a tool loop, place the message after the tool_result user message, never between an assistant tool_use and its tool_result (see Limitations). Once sent, the message is part of the prefix for later thinking: leave it in place on later requests.
Put changing context in the newest turn
Some harnesses put an environment block in the first user message (working directory, branch, date, memory, project instructions) and render it again on every request. When any value changes, messages[0] changes, and every thinking block in the conversation is invalid. Render that block once and resend it as it was. When a value changes, say so in the newest turn: add a text block to the user message you are about to send, or append a mid-conversation system message if the change comes from you as the operator.
{
  "role": "user",
  "content": [
    {
      "type": "text",
      "text": "Environment update: the current branch is now release-2."
    },
    { "type": "text", "text": "Run the tests again." }
  ]
}Once sent, that text block is part of the prefix for later thinking: leave it in place on later requests.
Send per-turn reminders as turn-scoped system messages
A common prefix edit is the per-turn nudge: a line such as "request independent reads together" or "you haven't updated the user in a while" that your code appends after each batch of tool results. To keep reminders from piling up, send each nudge as a mid-conversation system message with clear_at: "next_user_message", placed after the tool_result user message. clear_at requires the beta header mid-conversation-system-clear-at-2026-08-21. The following messages array is the request after two tool calls and their results. messages[3] is the previous request's nudge, left in place, and messages[6] is this request's copy:
[
  { "role": "user", "content": "Fix the failing test." },
  {
    "role": "assistant",
    "content": [
      { "type": "thinking", "thinking": "", "signature": "..." },
      {
        "type": "tool_use",
        "id": "toolu_01",
        "name": "read_file",
        "input": { "path": "tests/test_auth.py" }
      }
    ]
  },
  {
    "role": "user",
    "content": [{ "type": "tool_result", "tool_use_id": "toolu_01", "content": "..." }]
  },
  {
    "role": "system",
    "clear_at": "next_user_message",
    "content": "Request every independent read in one turn."
  },
  {
    "role": "assistant",
    "content": [
      { "type": "thinking", "thinking": "", "signature": "..." },
      {
        "type": "tool_use",
        "id": "toolu_02",
        "name": "read_file",
        "input": { "path": "src/auth.py" }
      }
    ]
  },
  {
    "role": "user",
    "content": [{ "type": "tool_result", "tool_use_id": "toolu_02", "content": "..." }]
  },
  {
    "role": "system",
    "clear_at": "next_user_message",
    "content": "Request every independent read in one turn."
  }
]A user message that contains only tool_result blocks counts as the "next user message", so messages[3] is already cleared. It adds nothing to what the model sees and costs no input tokens, but because it's still in the array, the thinking in messages[4] stays valid. messages[6] is the copy the model sees this turn. On later requests, keep both where they are and append a fresh copy after the next tool_result message.
Add or remove tools with tool_addition and tool_removal
Editing the tools array mid-session invalidates preserved thinking blocks. Instead, declare every tool the session might need in tools on the first request and never change the array. To change which tools the model can use from some point on, append a role: "system" message that carries a tool_removal or tool_addition block. These are mid-conversation tool changes and need the beta header mid-conversation-tool-changes-2026-07-01. For example, to withdraw a dangerous tool after a mode switch:
{
  "role": "system",
  "content": [
    { "type": "tool_removal", "tool": { "type": "tool_reference", "name": "delete_branch" } },
    { "type": "text", "text": "Branch deletion is disabled for the rest of this session." }
  ]
}To offer a tool later instead, declare it in tools with defer_loading: true so the model doesn't see it at first. When it becomes available, append a tool_addition block:
{
  "role": "system",
  "content": [
    { "type": "tool_addition", "tool": { "type": "tool_reference", "name": "deploy" } },
    { "type": "text", "text": "Authentication succeeded. Deployment is now available." }
  ]
}Sometimes you can't declare a tool up front because you don't know its schema yet. An MCP server discovered at runtime is the common case. Append that tool to tools with defer_loading: true, then offer it with a tool_addition block. Adding a deferred tool is safe: the prefix check ignores a deferred tool until a tool_addition block references it, so earlier thinking stays valid. Adding a tool without defer_loading: true changes the prefix and invalidates earlier thinking.
The role: "system" messages that carry these blocks join the prefix for later thinking. Leave them in place on later requests.
Change effort with a per-message output_config
Changing top-level output_config.effort between requests doesn't invalidate thinking, because effort isn't part of the prefix. Changing top-level effort does restart the prompt cache. On Claude Fable 5.1, use per-message effort instead: append a role: "system" message with empty content and the new level. It needs the beta header mid-conversation-output-config-2026-07-01.
{ "role": "system", "content": [], "output_config": { "effort": "low" } }The new level takes effect from the next user turn. Once sent, the message is part of messages and therefore part of the prefix for later thinking: leave it in place on later requests, and append another one to change effort again.
Trim context on the server
Another common prefix edit is client-side trimming: dropping or summarizing the oldest turns and keeping the recent ones verbatim. The kept turns' thinking blocks were produced while the removed history was still in place, so they fail the check. The server-side equivalents don't count as edits, because the check compares the conversation as you sent it:
- Compaction summarizes older turns into a compaction block when the context approaches a threshold you set, and the checked prefix restarts from that block. Its
instructionsparameter takes your own summarization prompt, such as "preserve every ticker, position size, and stated assumption". On-demand compaction (beta) returns the summary from a separate request, which can run in the background. Send"compaction": {"type": "summarize"}in the request body, and the response carries a singlecompactionblock, holding the summary and a signature, instead of a reply. On-demand compaction is available on the Claude API but not on Amazon Bedrock or Google Cloud, and it needs thecompact-2026-09-04beta header on the summary request and on every later request that carries the block. You send the block in place of the messages it summarizes. The check accepts that swap, so the turns you keep can stay valid with their thinking, under the conditions in Keep-tail compaction. - Context editing clears old tool results or old thinking blocks by rule, oldest first. The strategies are
clear_tool_uses_20250919andclear_thinking_20251015.
Compact on the client
You can still compact on the client. If you write the summary yourself, don't send back a thinking block that was produced before the rewrite. If the API writes it with on-demand compaction, Keep-tail compaction lists when kept thinking stays valid.
Simple compaction (recommended)
When the conversation grows too long, summarize the whole session into one user message and send only that message plus the next instruction. Nothing earlier is replayed, so there's no thinking left to fail the check, and the model reasons afresh from the summary.
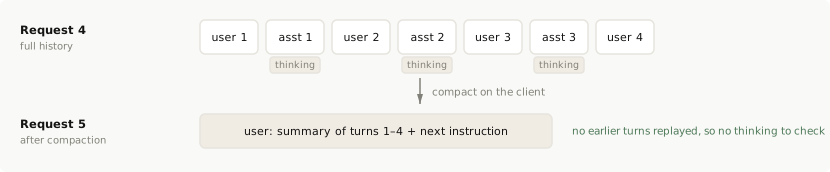
[
  {
    "role": "user",
    "content": "<summary of the session so far>\n\n<the next instruction>"
  }
]Claude models are trained on long-horizon tasks with this scheme and for most workloads it performs well.
Keep-tail compaction
Keep-tail compaction summarizes the older turns and keeps the most recent turns verbatim, so the model still sees the last few exchanges word for word. If you write the summary yourself, it breaks the rule: the kept assistant turns still carry thinking blocks that were produced when the original turns, not the summary, came before them. Those blocks fail.
To keep that thinking, have the API write the summary with on-demand compaction. Send only the older turns in a request with the compaction parameter and the compact-2026-09-04 beta header. Then send the signed block it returns in place of those turns, followed by the kept turns exactly as returned. The kept thinking stays valid while all of these hold:
- The compaction request runs on a model with preserved thinking. The conversation's own model is the simple choice.
- The kept turns directly follow the summarized messages, and the first kept message isn't one the API would merge into the last summarized one: a message with the same role, or a
role: "system"message. systemand your non-deferredtoolsmatch the compaction request.
The simplest way to meet the second is to compact exactly the messages of a request you already made. Mid-conversation system messages inside the summarized turns are summarized too, so their instructions and tool changes stop applying after the swap. To keep one in force, state it again in a role: "system" message directly after the first new user turn that follows the kept turns. A system message placed between the block and the kept turns breaks their thinking.
The rest of this section covers a summary you write yourself.
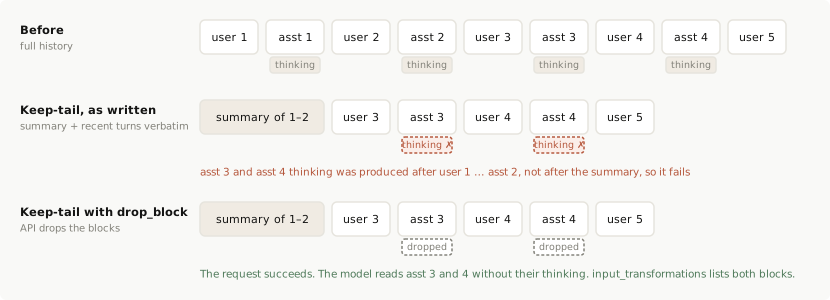
Fix: keep the turns exactly as they are and send prefix_mismatch_behavior: "drop_block". The API drops the stale thinking blocks, the model reads the kept turns' text and tool_use blocks, and the request succeeds.
Pass the compacted history as messages and set block_binding on the thinking configuration. In the following example, compacted_messages is the array your compaction step produced: the summary message followed by the kept turns exactly as the API returned them, thinking blocks included:
client = anthropic.Anthropic()

# compacted_messages: the summary message, then the kept turns as returned
response = client.beta.messages.create(
    model="claude-fable-5-1",
    max_tokens=16000,
    thinking={
        "type": "adaptive",
        "block_binding": {"prefix_mismatch_behavior": "drop_block"},
    },
    messages=compacted_messages,
    betas=["thinking-binding-controls-2026-08-01"],
)

print(response.input_transformations)
The response carries the new assistant turn as usual, plus one input_transformations entry per dropped block. For the history in the diagram, that's the thinking on assistant turns 3 and 4:
{
  "input_transformations": [
    {
      "type": "thinking_dropped",
      "path": "messages.2.content.0",
      "reason": "prefix_binding_mismatch"
    },
    {
      "type": "thinking_dropped",
      "path": "messages.4.content.0",
      "reason": "prefix_binding_mismatch"
    }
  ]
}Keep sending "drop_block" on later requests for as long as those two turns stay in the history. Thinking the model produces from this request onward follows the summary and stays valid. If you'd rather not depend on the beta header, the alternative is to strip the thinking and redacted_thinking blocks from the kept assistant turns yourself when you build the compacted history.
Background (async) compaction
Background compaction builds the summary off the critical path while the conversation continues, then swaps it in a few requests later. Have the API write the summary with on-demand compaction:
- Send the conversation so far in a separate request with the
compactionparameter and thecompact-2026-09-04beta header. - Keep working on the full history while that request runs.
- On the first request after the block arrives, send it in place of the messages the compaction request held, followed by every turn appended since.
The thinking produced while the summary was being built stays valid under the same conditions as in Keep-tail compaction.
A summary you build yourself breaks the rule the same way keep-tail does, with a delay: every assistant turn produced while the summary was being built carries thinking that predates the swap, and it all fails the moment the summary lands. If you use one, treat the swap like keep-tail and send "drop_block" from the swap onward, or compact synchronously.
Patterns that don't work with preserved thinking
- Cutting turns out of the middle. Removing individual turns invalidates every thinking block after them, and no compaction scheme avoids that. If you were cutting a turn to change an instruction, append a mid-conversation system message instead. To remove old tool results or old thinking selectively, use server-side context editing.
- Compacting in the middle of a tool round. Don't compact between an assistant turn's
tool_useand thetool_resultthat answers it. Send that assistant turn back with its thinking intact so the model finishes the round with its reasoning. See Preserving thinking blocks.
Reference files by ID, not by a URL whose content changes
For an image or document block with a url source, the check covers the fetched bytes, not the URL string. A URL whose content changes invalidates later thinking: a "latest screenshot" endpoint, or a document someone edits between turns. A rotating signed URL for the same file doesn't. For content you reference across turns, upload it once with the Files API and use the file_id, or send base64.
Libraries, proxies, and gateways
A library, proxy, or gateway sits between someone else's history and the API, so its own rewrites count as edits, and its users can't see or fix them.
- Pass through what you don't recognize. Forward the caller's
anthropic-betavalues andthinking.block_bindingunchanged, and returninput_transformationsto them. An options schema that rejects unknown keys stops your users from choosing"drop_block". - Leave a
role: "system"message where the caller put it. Moving it into the top-levelsystemfield changessystemon that request and invalidates every thinking block in the conversation. - To turn tool use off for a request, send
tool_choice: {"type": "none"}. Don't removetools. - Don't hide the 400. If your code catches it, strips thinking, and retries on the caller's behalf, log that it did: their history is still edited, and the model loses its earlier reasoning on every later request.
FAQ
No. Send the thinking-binding-controls-2026-08-01 beta header and set thinking.block_binding.prefix_mismatch_behavior. Setting the field opts that request into enforcement regardless of account age. "error" rejects an edited history with the same 400 a new account gets, and "drop_block" lets the request through and lists what was dropped in input_transformations. See Check whether your code edits the prefix.
No. What fails is the thinking already in the history after the point you changed, and you choose what happens to it. With prefix_mismatch_behavior: "drop_block", the API drops those blocks and the request succeeds: the model answers that turn without that reasoning, and the prompt cache restarts at the edit. With the default "error", the API rejects the request with a 400 until you undo the edit or resend with "drop_block". See What the API does with an invalid block. What counts as an edit lists which changes matter.
No. output_config.effort, max_tokens, and the thinking configuration aren't part of the checked prefix, which covers only system, tools, and messages. A top-level effort change invalidates most of the prompt cache. On Claude Fable 5.1, a per-message effort change keeps the prompt cache and is used as the new effort level until changed again.
Don't edit tools. Declare the full set at session start, mark tools that aren't available yet with defer_loading: true, and offer or withdraw them with tool_addition and tool_removal blocks. If you learn a tool's schema only mid-session, such as from an MCP server discovered at runtime, you can still append it to tools with defer_loading: true and offer it the same way. That's safe because an unreferenced deferred tool isn't part of the prefix. The role: "system" messages that carry these blocks join the prefix for later thinking, so don't move, reword, or delete them afterward. See Add or remove tools with tool_addition and tool_removal.
Yes, if the API writes the summary. On-demand compaction (beta header compact-2026-09-04) summarizes the older turns into a signed block that you send in place of them. The recent turns keep their thinking under the conditions in Keep-tail compaction.
If you write the summary yourself, the kept turns' thinking fails the check, because those blocks were produced against the history you replaced. Strip thinking and redacted_thinking blocks from the turns you carry across and keep their text and tool_use blocks, or send prefix_mismatch_behavior: "drop_block" and let the API drop them. Simple compaction leaves no thinking behind to fail and is the recommended approach: one summary message plus the next user turn, with no earlier turns replayed. Server-side compaction and context editing don't count as edits. See Compact on the client.
Load them once at session start and keep the top-level system prompt and tools fixed. When a file changes, append the new version at that point in messages instead of editing the original. Use a mid-conversation system message for instructions that come from you as the operator. For file text you treat as untrusted, which shouldn't carry system-prompt authority, put the content in the next user turn instead. See Add instructions with a mid-conversation system message and Limitations.
Yes. A resumed session is an ordinary follow-up request: system, tools, and the earlier messages must have the same content as what you last sent. JSON formatting and key order don't matter; the values do. Persist exactly what you sent and received, and replay that: the rendered system prompt, the tool definitions, and each assistant turn as returned. Don't re-render from inputs that might have changed since, such as the date, an updated instruction file, or a new tool version. Anything new goes in an appended message. See Send assistant turns back exactly as returned.
The stored history has an edit in it, so replaying it can't succeed. Send that session with prefix_mismatch_behavior: "drop_block" from now on, or remove its thinking and redacted_thinking blocks once and continue. Thinking the model produces from that point on stays valid as long as nothing before it changes again. Then find the edit so that new sessions don't hit it. See Handle the error in code.
No, provided they're appended after the existing history and nothing earlier changes: an assistant message without thinking blocks is an appended message like any other. Send the other model's output as text and tool_use content.
Not into a different conversation. A thinking block is usable only when it follows the exact system, tools, and messages it was produced from. A branch that replays that history unchanged up to the fork point keeps its thinking. A conversation that starts from anything else can't use it, so start that conversation from a summary of the task state, as in simple compaction: the goal, decisions made, files and results so far, and the next step.
Next steps
Diagnose and fix the most common thinking failures: configuration 400 errors, empty or missing thinking blocks, max_tokens stops, and cache misses.
Change system instructions or tool availability partway through a conversation without invalidating the cached prefix that came before them.
Server-side context compaction for managing long conversations that approach context window limits.
Cache prompt prefixes with cache_control to cut costs and latency, using automatic caching or explicit breakpoints with 5-minute or 1-hour TTLs.
Was this page helpful?
