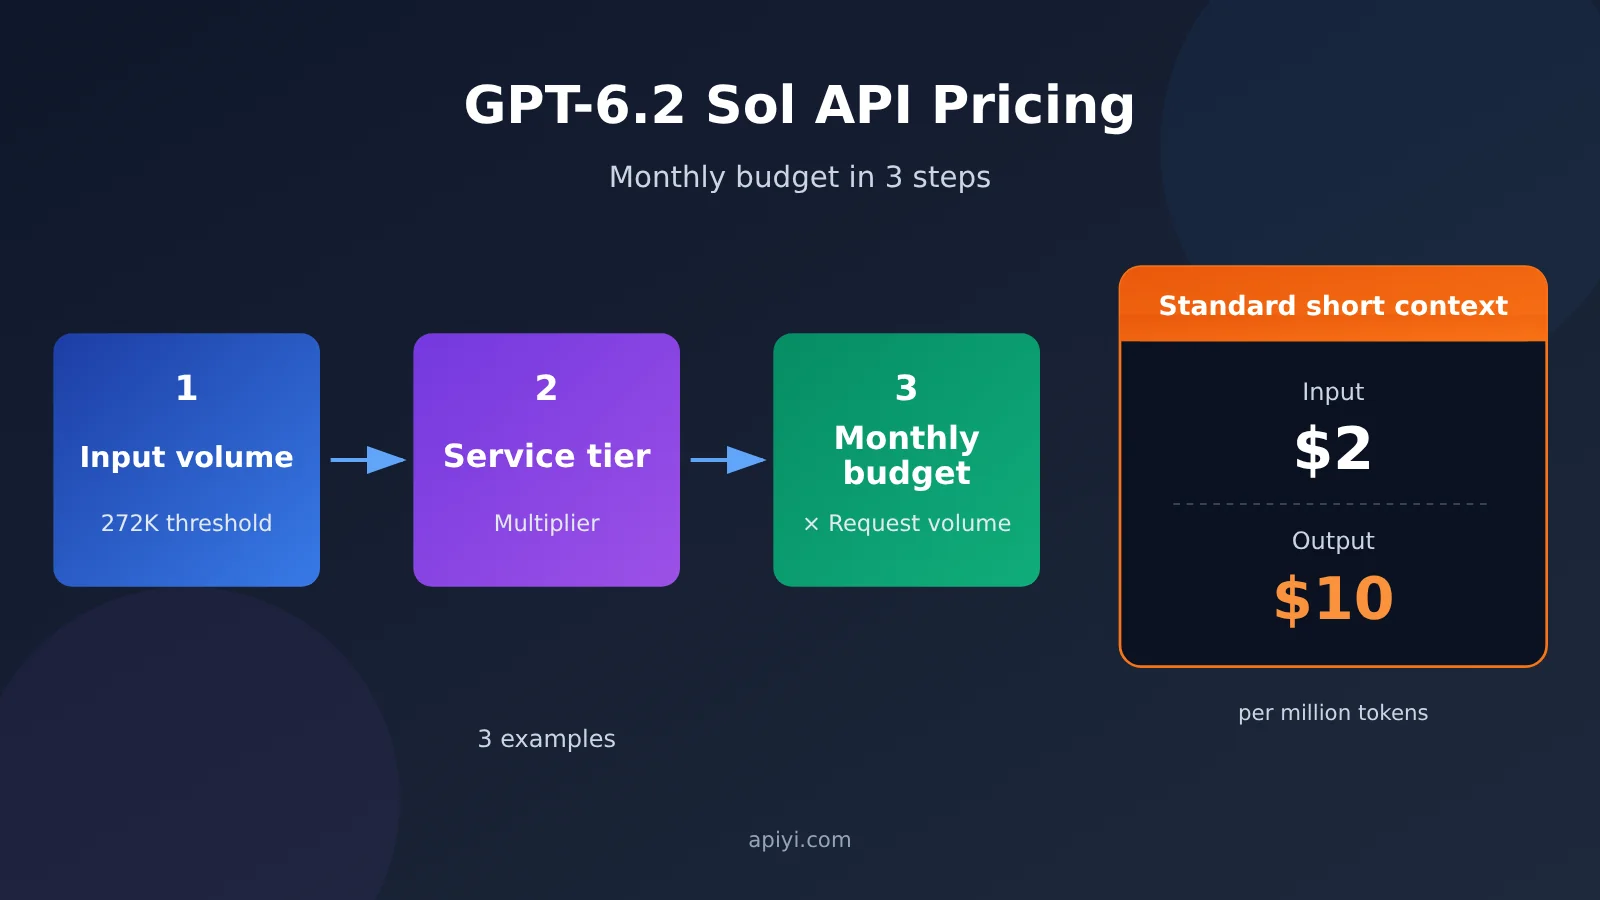
Calling the API for GPT-6.2 Sol comes down to three steps when it’s time to figure out the bill. Step one looks at the total input volume of a single request, using 272K tokens as the line between short and long context; once you cross that threshold, the input and cache rates for the entire request are multiplied by 2, and output by 1.5. Step two picks a service tier based on your delivery deadline: Standard is the baseline price, Batch is 50% off, the background 8h and 2h windows bill at 60% and 70% respectively, Fast is 2×, and Ultrafast is 3× until 2027-02-28 (Pacific Time) and 6× after that. Step three multiplies the per-request cost by your monthly request volume, then adds tool calls, any applicable regional fees, and retries.
Short-context Standard list prices: regular input at $2.00 per million tokens, cached reads at $0.10, and output (including reasoning tokens) at $10.00. At those rates, an interactive request with 20,000 input tokens and 3,000 output tokens comes to about $0.07, or roughly $140 for 2,000 requests a month. All prices in this article are in USD per million tokens, verified on 2026-11-20 (Beijing time).
GPT-6.2 Sol API Billing Knowledge Map and Reading Index
The whole article unfolds in this order: input volume check → delivery deadline tier selection → cumulative usage. The table below puts the question each step answers, the output, and the section number side by side. The output of each section becomes the input for the next.
| Step | Question to answer | Output of this step | Section |
|---|---|---|---|
| Input volume check | Does this request fall into short context or long context? | Applicable base rate table | 1, 3.2 |
| Delivery deadline tier | Are users waiting online, or can delivery happen hours later or next day? | Service tier multiplier | 2, 3.1 |
| Cumulative usage | How many requests per month, and what other add-on costs are there? | Monthly budget | 2, 4 |
| Channel recalculation | If you switch to another billing channel, how much does the same request cost? | Channel comparison and budget table | 4 |
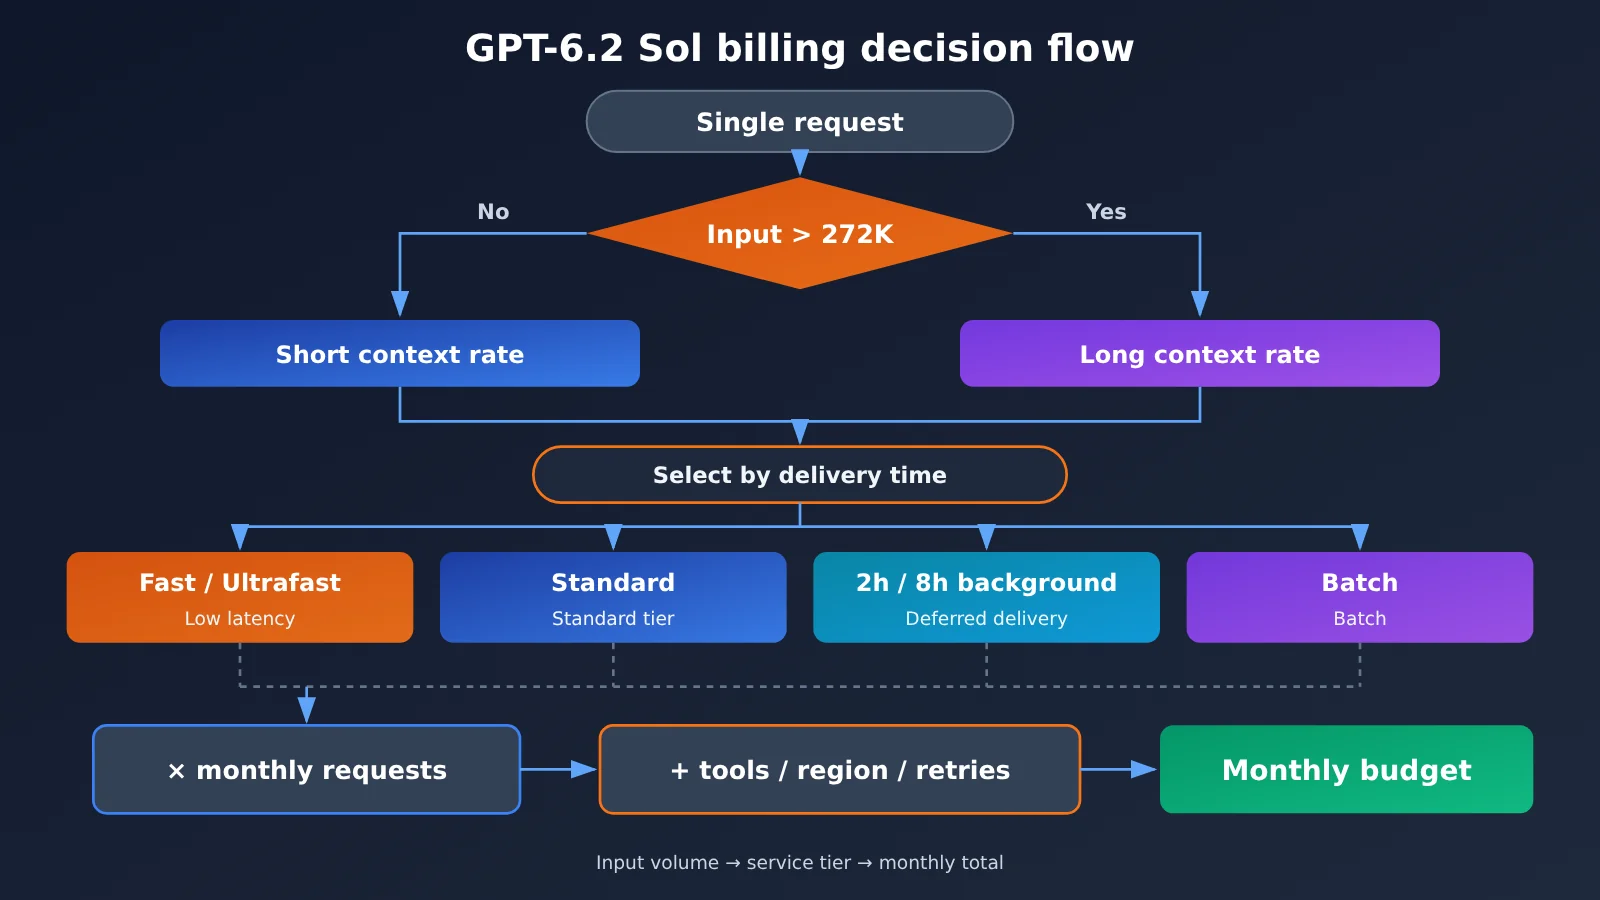
For reading order, Section 1 gives the base rates and is the basis for every worked example that follows. Sections 2 and 3 cover two types of business—”users waiting online for results” and “delayed delivery allowed”—so you can read only the section that applies to you. Section 4 applies the earlier calculations side by side to the public pricing at APIYI apiyi.com and OpenAI’s official rates, then ends with a monthly budget table you can fill in directly.
GPT-6.2 Sol Billing Terms to Know
| Term | Explanation |
|---|---|
| Token | The basic unit the model uses to measure text and other input/output; counts are based on server-returned statistics. |
| Standard | The regular processing tier for the official API and the pricing baseline for other tier multipliers. |
| Cache read | When a request reuses a previously cached history prefix, that input is billed at the cache-read rate. |
| Cache write | A separate billing category for saving eligible prefixes for future reuse, with 30-minute and 12-hour options. |
| Billed output | Output volume counted by the API, including reasoning tokens and final output. |
| Batch API | An interface for submitting a prepared set of independent requests as a file for background batch processing. |
| Completion window | The target time limit set for the initial response after a background request is accepted. |
| Fast and Ultrafast | Two higher-rate tiers for low-latency scenarios. |
1. What does a single GPT-6.2 Sol API request cost?
1.1 The five billing categories in the Standard tier
GPT-6.2 Sol’s API model ID is gpt-6.2-sol, and you can call it through either the Responses or the Chat Completions endpoint. A single request can touch up to five billing categories, and the table below shows the official Standard-tier list prices. Short-context base pricing matches GPT-6.1 Sol, while the long-context column uses the multipliers from the model card.
| Standard billing category | Short context (≤272K input) | Long context (>272K input) |
|---|---|---|
| Regular input | $2.00 | $4.00 |
| Cache read | $0.10 | $0.20 |
| 30-minute cache write | $2.50 | $5.00 |
| 12-hour cache write | $5.00 | $10.00 |
| Output (reasoning tokens included) | $10.00 | $15.00 |
Three things in the table are easy to get wrong.
- Cache writes don’t stack on top of regular input. The batch of tokens written to cache is charged once at the full 30-minute or 12-hour rate and isn’t billed again as regular input.
- Reasoning tokens count as output. The
usage.output_tokensreturned by Responses is the total output; reasoning usage typically shows up as a sub-item inoutput_tokens_details.reasoning_tokens, so just budget against the total. - The tier switch applies to the whole request. Once total input crosses 272K, the input, cache, and output for the entire request all move to long-context rates — it isn’t a surcharge on just the portion above 272K.
The model card also lists a 1,050,000-token context window, a 922,000-token maximum input, and a 128,000-token maximum output. 922K is the largest input allowed; 272K is the billing tier point. The two are unrelated.
1.2 Costs beyond the model fee
The table above covers only model token fees. Inside Responses, Sol can call tools like file search, web search, code interpreter, and image generation, and each of these is billed under its own separate rules when actually used. When you generate images, Sol makes the tool call and a separate image tool produces the images, so image costs are billed separately. If you deploy in a particular region, applicable regional fees may also apply. Give these items their own columns in your budget sheet rather than folding them into the per-token price.
1.3 Reading actual billed usage with code
Once you’ve estimated, calibrate against the usage field of real requests. The example below calls Sol through an OpenAI-compatible endpoint and converts that one request’s cost using short-context Standard rates:
from openai import OpenAI

client = OpenAI(
    api_key="YOUR_API_KEY",
    base_url="https://api.apiyi.com/v1"  # APIYI OpenAI-compatible endpoint
)

resp = client.responses.create(
    model="gpt-6.2-sol",
    input="用三句话说明 Batch API 适合什么任务。"
)

u = resp.usage
cached = getattr(getattr(u, "input_tokens_details", None), "cached_tokens", 0) or 0
plain_in = u.input_tokens - cached
cost = (plain_in * 2.00 + cached * 0.10 + u.output_tokens * 10.00) / 1e6
print(resp.output_text)
print(f"输入 {u.input_tokens},其中缓存 {cached},输出 {u.output_tokens},模型费约 ${cost:.6f}")
This conversion applies only to Standard requests with input under 272K and no cache writes. In production, you’ll want to log the usage from every request, aggregate by task type, and then fill in the budget table in Section 4.
🎯 Official recommendation: Before locking in a budget, run 20 to 50 real business requests through and look at the distribution of input and output. New APIYI apiyi.com users get free trial credits, which makes it a good fit for this kind of small-sample calibration.
2. How GPT-6.2 Sol Interaction Tiers and Monthly Budgets Are Calculated
2.1 Cost of the Same Request Across Three Interaction Tiers
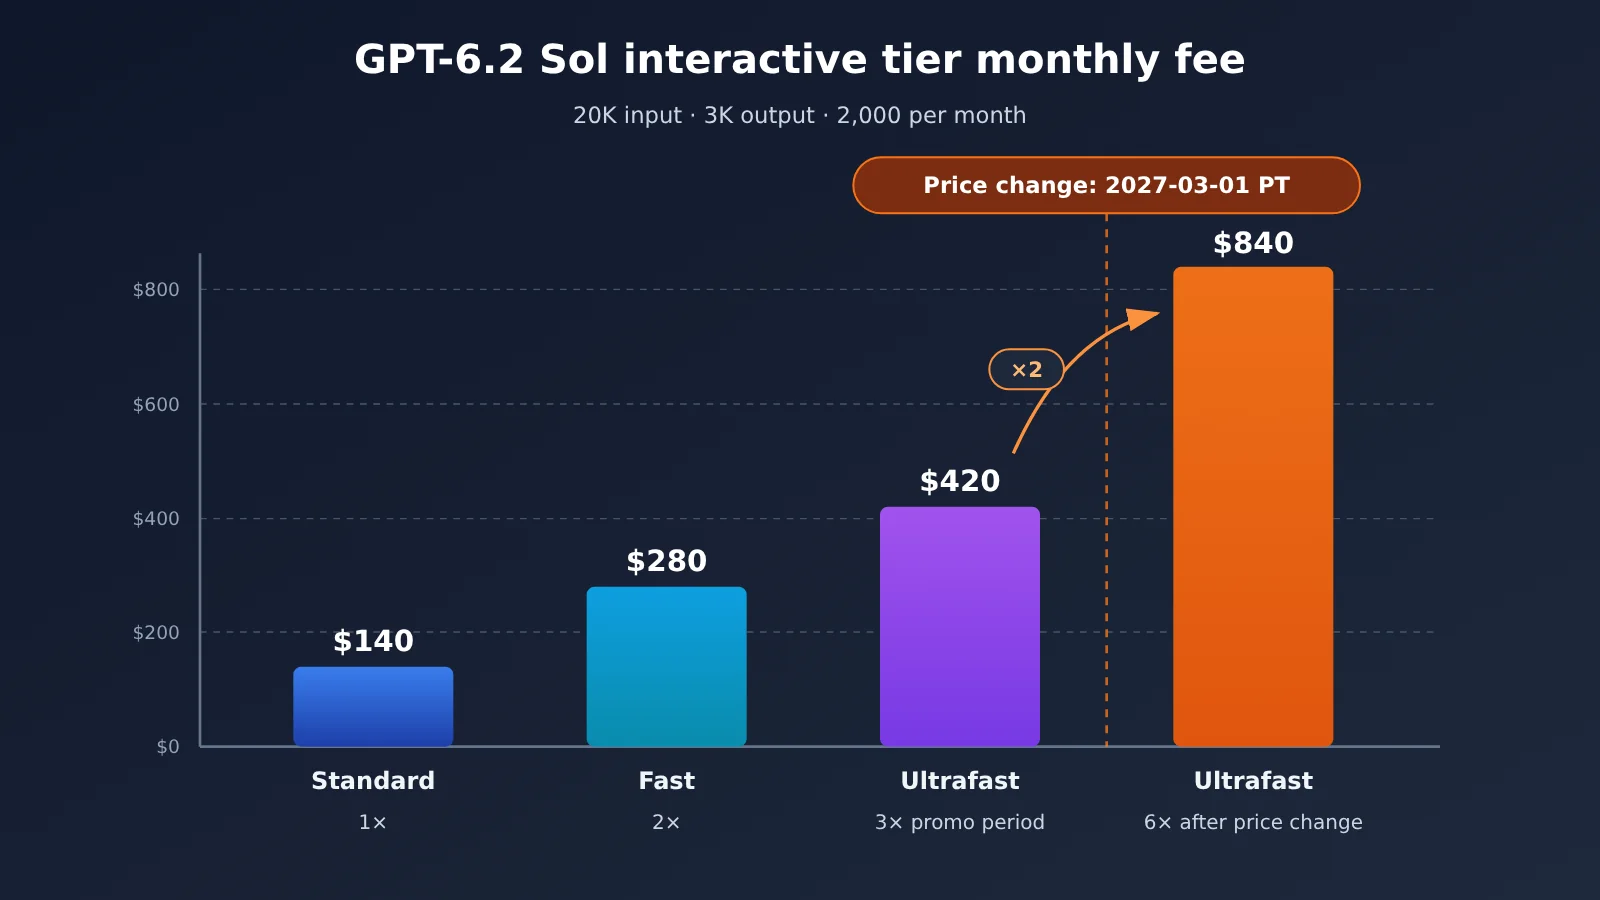
In interactive scenarios, users wait for results in the UI and can choose Standard, Fast, or Ultrafast. Fast is billed at 2× the Standard rate. Ultrafast is 3× through 2027-02-28 (Pacific Time) and 6× from 2027-03-01 onward. GPT-6.2 Sol doesn’t support the Flex tier.
The worked example assumes one request has 20,000 regular input tokens and 3,000 billable output tokens, with no caching, tools, regional fees, or retries, at 2,000 requests per month. The Standard cost per request is 20000×2/1e6 + 3000×10/1e6 = $0.07.
| Service tier | Multiplier | Cost per request | 2,000 requests/month |
|---|---|---|---|
| Standard | 1× | $0.07 | $140 |
| Fast | 2× | $0.14 | $280 |
| Ultrafast (through 2027-02-28 PT) | 3× | $0.21 | $420 |
| Ultrafast (from 2027-03-01 PT) | 6× | $0.42 | $840 |
2.2 Conditions to Keep in Mind When Reading This Table
The table fixes usage per request to make budgeting easier. In reality, token consumption and latency for the same task will vary by request across tiers, so before launch you should run a batch of real requests on each candidate tier to verify.
If you’re budgeting for Ultrafast before March 2027, prepare a version calculated at 6× as well. In this example, the monthly fee goes from $420 to $840 after the price change, which takes effect on March 1, Pacific Time—March 1 afternoon in Beijing time.
💡 Tier selection tip: Launch most interactive requests on Standard first, and switch only latency-sensitive entry points to Fast or Ultrafast. Test in parallel through APIYI apiyi.com with the same API key to get real latency and usage data across tiers more quickly.
3. How to estimate costs for GPT-6.2 Sol overnight processing and long documents
3.1 Overnight batch jobs: 2h, 8h, and Batch
There are three discounted ways to handle tasks that don’t need to return results immediately. The Responses background mode’s 2h and 8h completion windows are billed at 70% and 60% of the Standard model token rate respectively, but requests must be Standard and non-streaming, and the window refers to the target time for the initial response; soonest gets no window discount. The Batch API bills at 50% of Standard, submits requests in bulk as files, and has a 24-hour turnaround window.
The worked example assumes 10,000 requests in total, each with 50,000 normal input tokens and 4,000 billable output tokens, with no caching and no tools. A single Standard call costs 50000×2/1e6 + 4000×10/1e6 = $0.14.
| Method | Rate | Cost per call | Total for 10,000 | When to use |
|---|---|---|---|---|
| Standard | 100% | $0.14 | $1,400 | You need results as soon as possible |
Background 2h |
70% | $0.098 | $980 | The app needs the initial response within two hours and has to feed tool results back in mid-task |
Background 8h |
60% | $0.084 | $840 | Submit that night, deliver before the next workday, and still need step-by-step interaction |
| Batch API | 50% | $0.07 | $700 | Requests are already prepared, independent of each other, and can be delivered the next day |
You can organize this by task shape. For tasks like classification and extraction that are independent of each other and can be fully written out before submission, treat Batch as the price baseline. For tasks where the app has to supply tool results mid-task before continuing, estimate each step separately, then pick the 2h or 8h window based on the app’s overall delivery deadline.
There’s also a capacity constraint: discounted background requests and Batch share a separate queue quota. Before planning a large batch submission, check the backlogged input token quota so requests don’t get stuck in the queue.
3.2 Long documents: the cost jump when you cross 272K
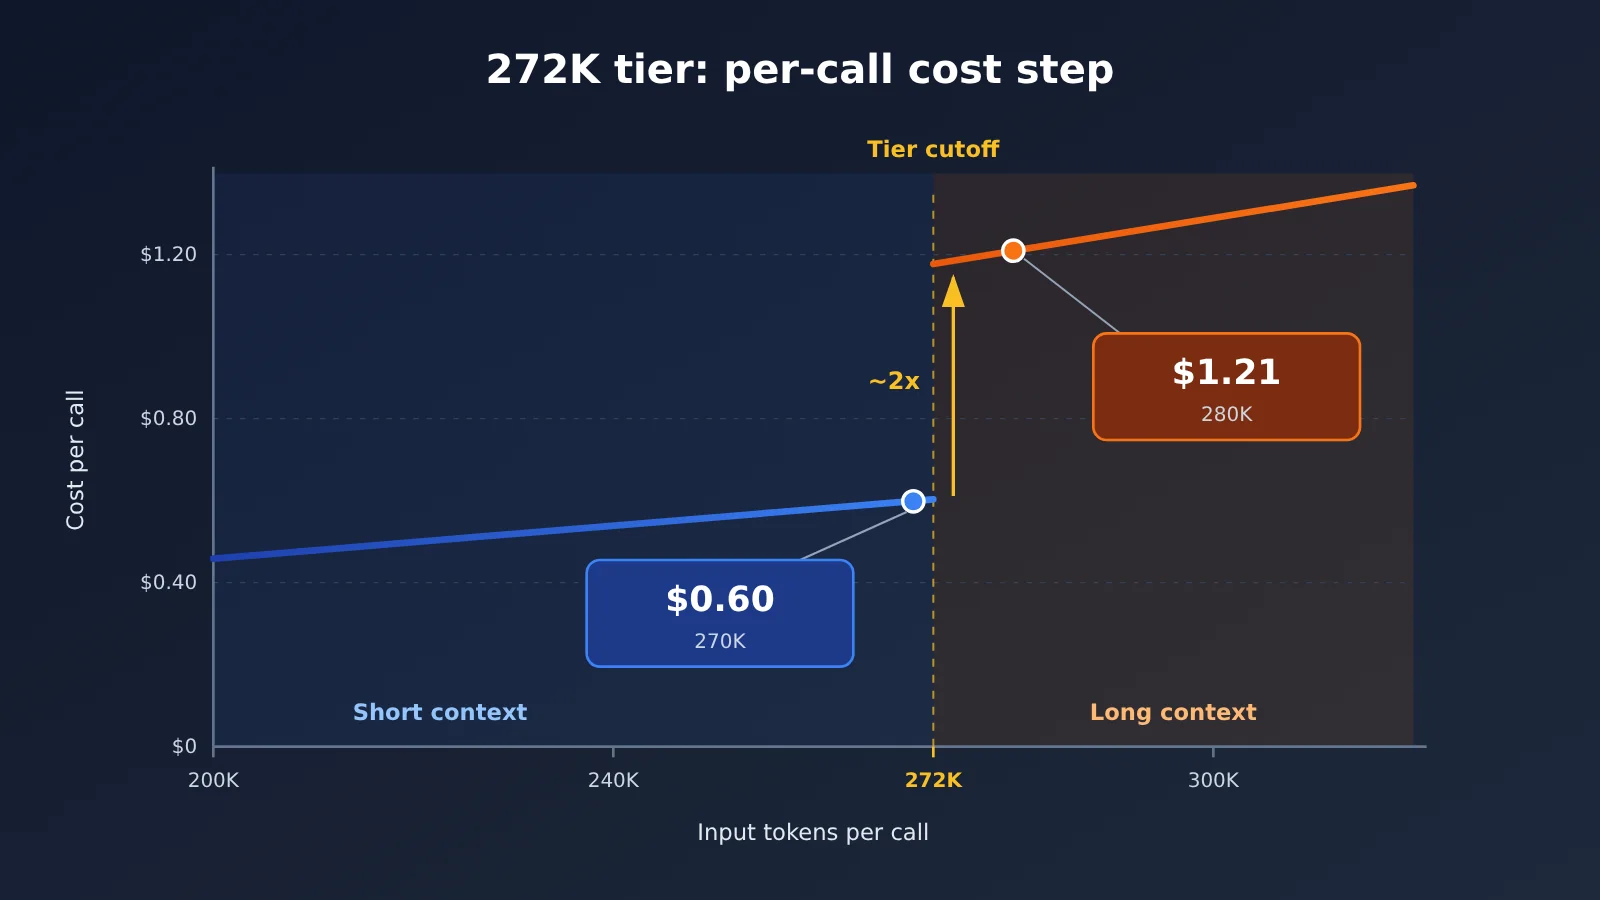
The cost jump for long documents comes from the tiering rule. The example assumes no caching and no tools, a fixed output of 6,000 tokens, the Standard tier, and inputs of 270,000 and 280,000 respectively:
| Input size | Applicable rate | Calculation | Model cost per call |
|---|---|---|---|
| 270,000 | Short context | 270000×2/1e6 + 6000×10/1e6 |
$0.60 |
| 280,000 | Long context | 280000×4/1e6 + 6000×15/1e6 |
$1.21 |
The input is only 10,000 tokens larger, yet the cost per call goes from $0.60 to $1.21 — roughly double. The reason is that the entire request is repriced at the long-context rate, and the output unit price also goes from $10 to $15.
When budgeting, record the input distribution of each request by business queue, estimate normal requests and long-document peaks separately, then add them up. If you plan to trim documents to push input below 272K, you must also verify that the trimmed content still retains the evidence needed for delivery — otherwise the money you save may have to be paid back in rework.
4. Fill in the GPT-6.2 Sol Monthly Budget by Channel
4.1 Side-by-Side Recalculation: APIYI Public Pricing vs. OpenAI Official Rates
Reading back APIYI’s public model table and public pricing endpoint on 2026-11-20, gpt-6.2-sol shows up in both, and the table lists two entry points: responses and chat. Public pricing also splits tiers at 272,000 input tokens, but the pricing expression for the long tier differs from the official multipliers.
| Billing category (USD / million tokens) | OpenAI short tier | OpenAI long tier | APIYI apiyi.com short tier | APIYI apiyi.com long tier |
|---|---|---|---|---|
| Standard input | $2.00 | $4.00 | $2.00 | $3.00 |
| Cache read | $0.10 | $0.20 | $0.10 | $0.15 |
| Cache write | $2.50 (30 minutes) | $5.00 (30 minutes) | $2.50 | $3.75 |
| Output | $10.00 | $15.00 | $10.00 | $11.25 |
Using the same usage recalculation as section 3.2: at 270,000 input and 6,000 output, both channels come out to $0.60. At 280,000 input and 6,000 output, OpenAI official charges $1.21, while APIYI’s public formula gives (280000×3 + 6000×11.25)÷1e6 = $0.9075 — roughly $0.30 difference per call. The higher the share of long documents, the bigger this gap weighs on your monthly budget.
The differences above are derived purely from the parameters both sides have published. The Batch and background-window discounts discussed earlier used OpenAI’s official worked examples; when you call through APIYI, account grouping, actual charges, available tiers, and API capabilities are subject to APIYI’s current configuration and billing.
4.2 A Monthly Budget Table with One Row per Task Type
Now let’s put the earlier formulas onto a single table: one row per task type, filled in with the average usage per request, then multiplied by the number of monthly requests. When a workflow involves multiple model invocations (for example, multi-step reasoning in an Agent), record each step as a separate row and add them up at the end.
| Task Type | Monthly Requests | Avg. Regular Input | Avg. Cache Read | Cache Write (Tier) | Avg. Billed Output | Context Tier | Service Tier | Additional Charges (Tools / Region) | Expected Retry Rate | Monthly Cost |
|---|---|---|---|---|---|---|---|---|---|---|
| Customer Support Interaction | 2,000 | 20,000 | 0 | 0 | 3,000 | Short | Standard | None | 0% | $140 |
| Nightly Classification | 10,000 | 50,000 | 0 | 0 | 4,000 | Short | Batch | None | 0% | $700 |
| Contract Review | Fill in as actual | Fill in as actual | 6,000 | Long | Standard | Fill in as actual | Fill in as actual |
The numbers in the first two rows come from the worked examples in this article, so you can use them as a reference when filling in your own. The monthly cost formula is “per-request model fee × monthly request count × (1 + retry rate) + additional charges.” The per-request model fee should be taken from the rate table in Section 1, based on the context tier and service tier for that row.
🚀 Practical Tip: Once the budget table is filled out, pick the two task types with the highest costs and run a round of real requests for each on APIYI apiyi.com. Replace the estimates with the actual values from
usage, and you’ll have a budget you can hand to finance.
4.3 Check whether your budget is reliable
Once you’ve got your first month’s bill, go through it line by line and check three things.
- Whether the share of requests exceeding 272K matches your estimate in the actual input distribution.
- Whether the proportion of reasoning tokens within
output_tokensis significantly higher than during the testing phase. - Whether retries and tool calls were actually counted.
If all three deviations are within 10%, you can carry this table straight into next month; whichever one is off by more is the first place you’ll need to adjust usage or tier.
References
- OpenAI official API pricing: per-service-tier multipliers plus Batch and background window discounts
- Link:
developers.openai.com/api/docs/pricing
- Link:
- GPT-6.2 Sol model card: context window, 272K tier-splitting rules, and limits
- Link:
developers.openai.com/api/docs/models/gpt-6.2-sol
- Link:
- Background mode and Batch API guides: completion windows, non-streaming requirements, and queue quotas
- Link:
developers.openai.com/api/docs/guides/background,developers.openai.com/api/docs/guides/batch
- Link:
- APIYI model list and public pricing endpoint: the
gpt-6.2-sollisting entry and tier pricing expressions- Link:
docs.apiyi.com/models.md,api.apiyi.com/api/pricing
- Link:
Author: APIYI technical team
Technical support: For questions about billing rules and account configuration, contact us via the APIYI homepage; for more integration resources, see the docs.apiyi.com documentation center